AI大模型微调教程2
·
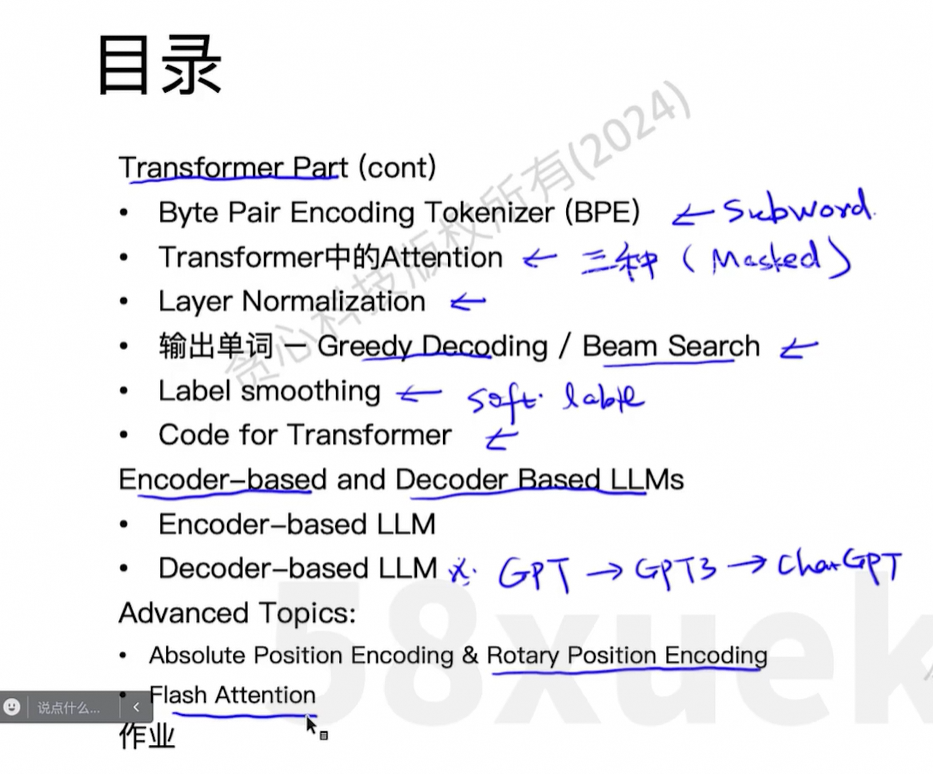
第1节课:Transformer Part1
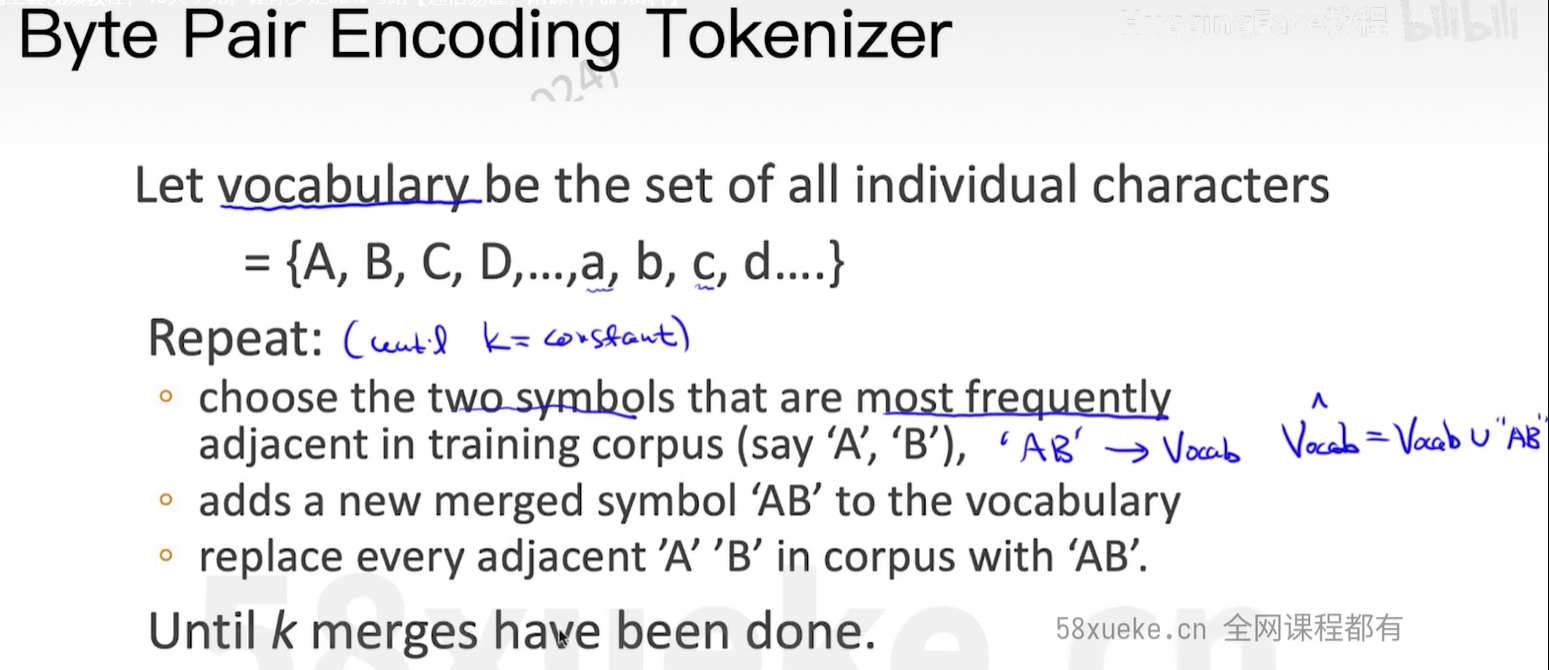
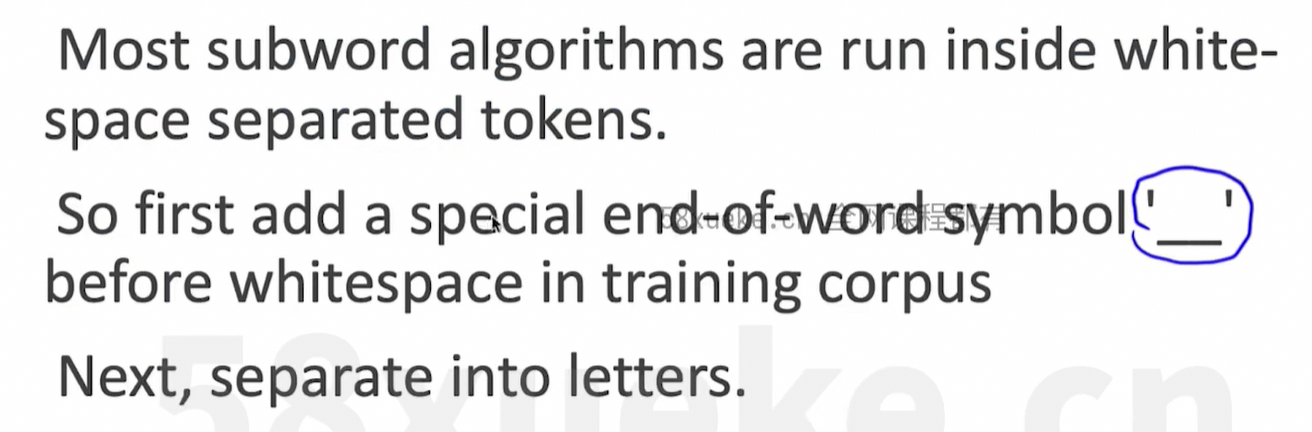
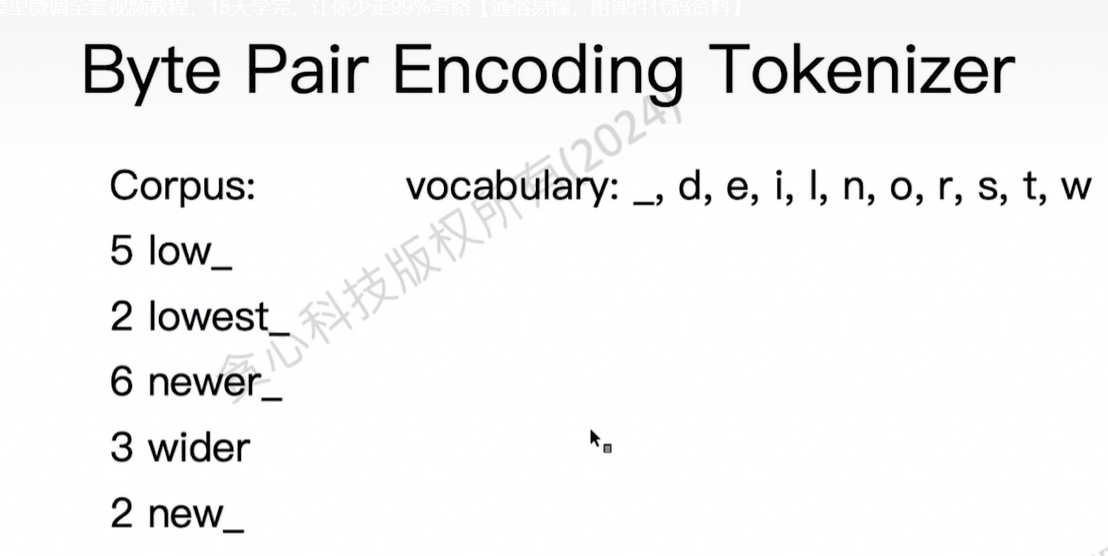
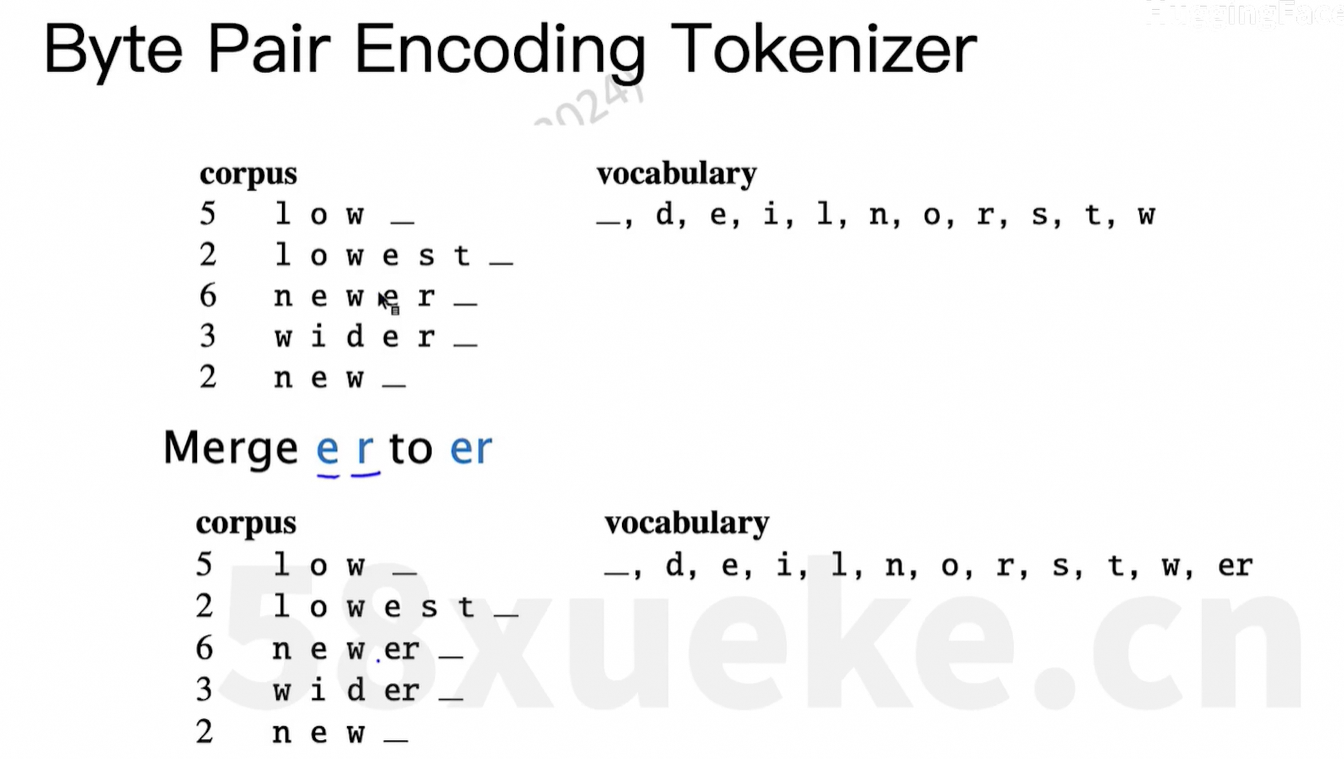
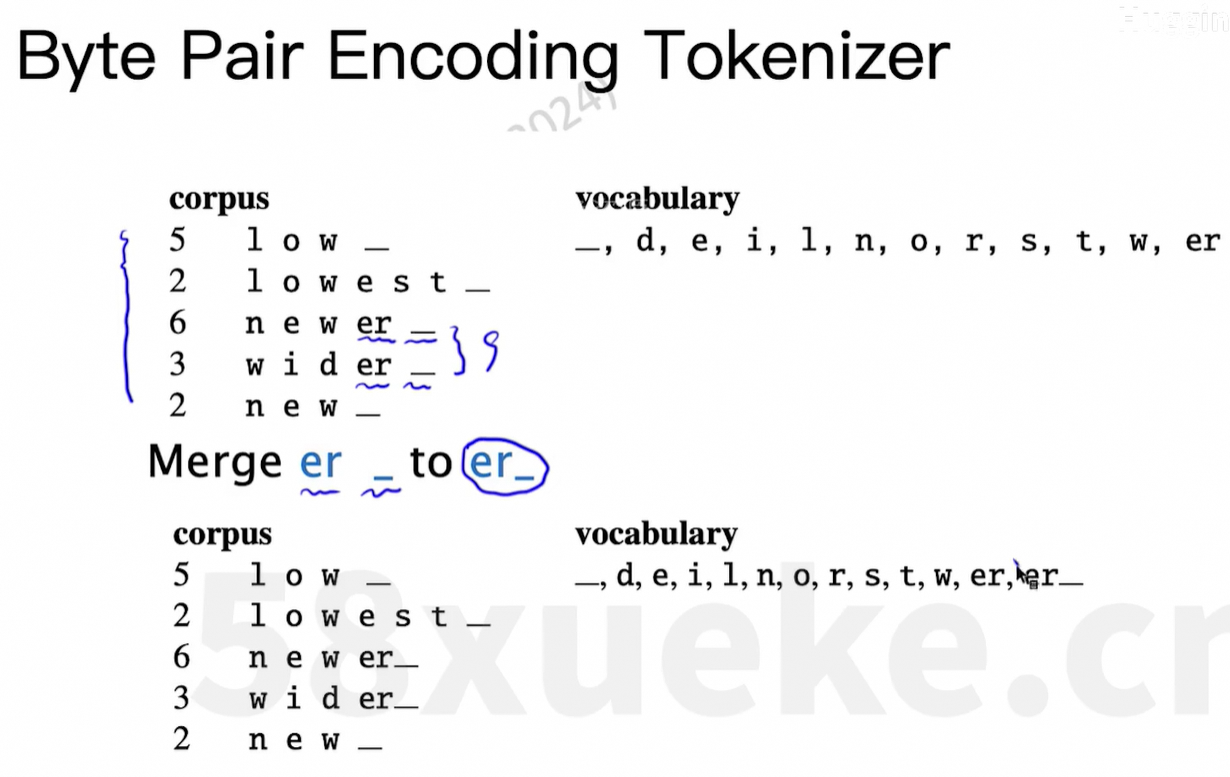
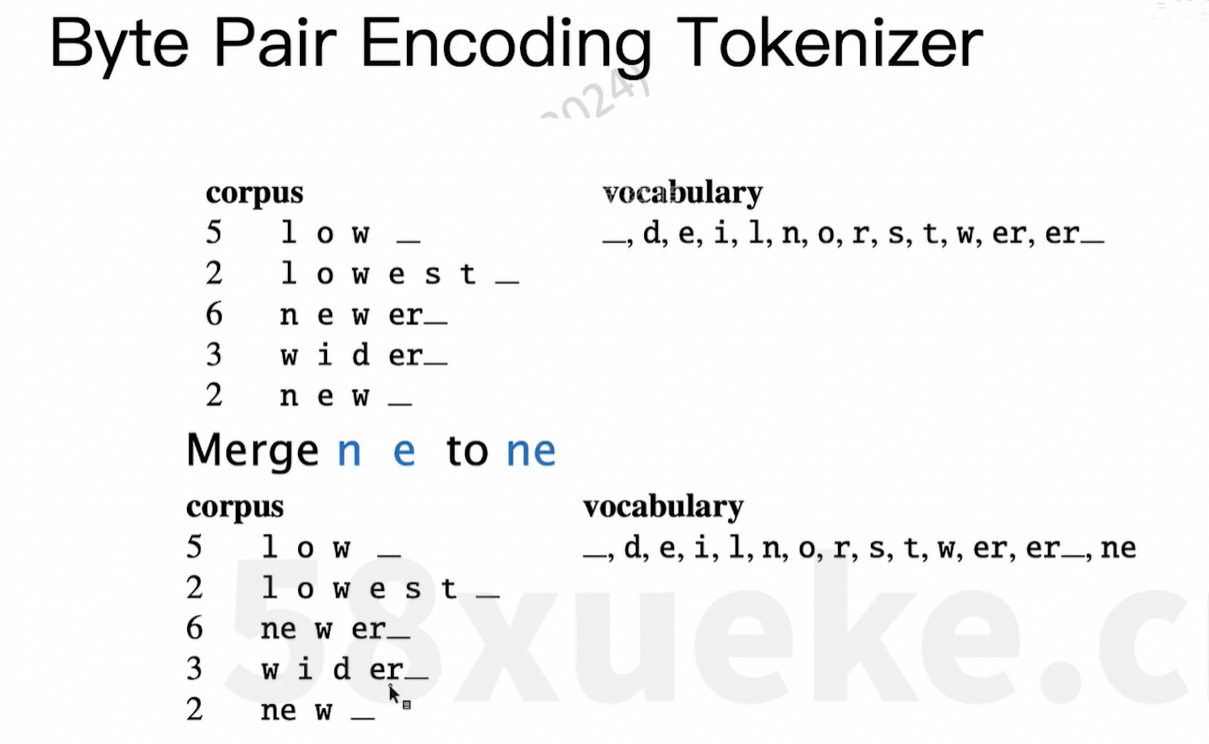
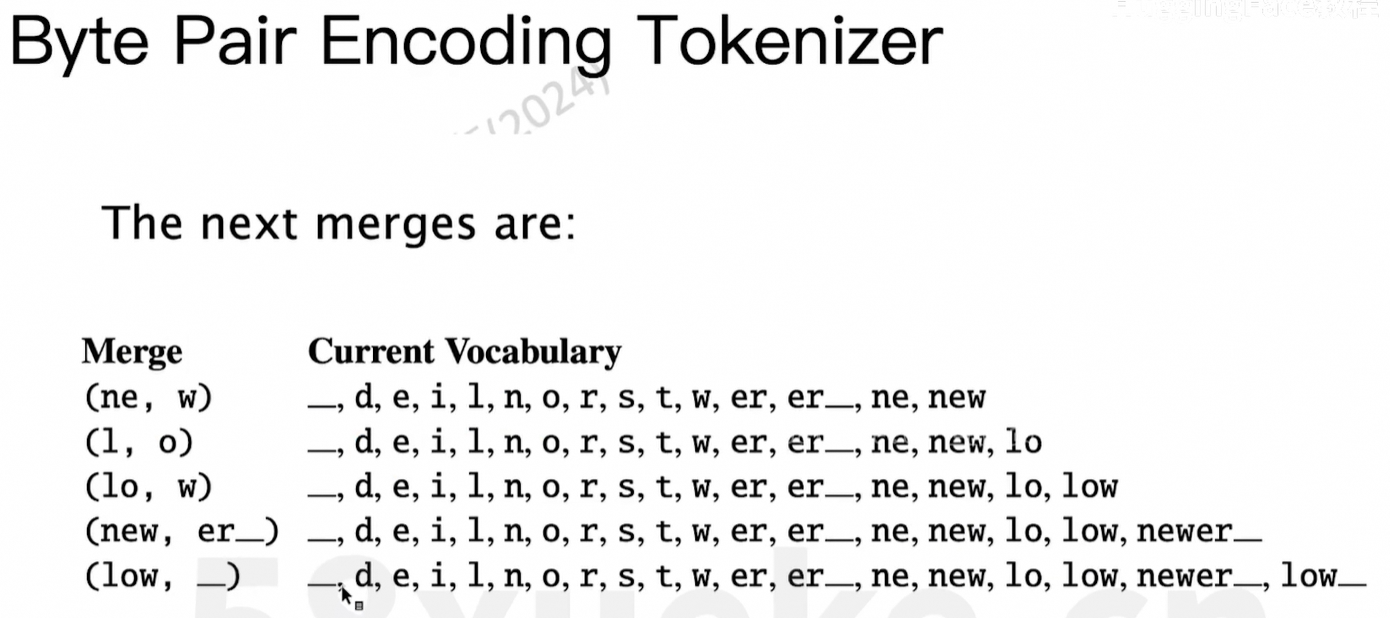
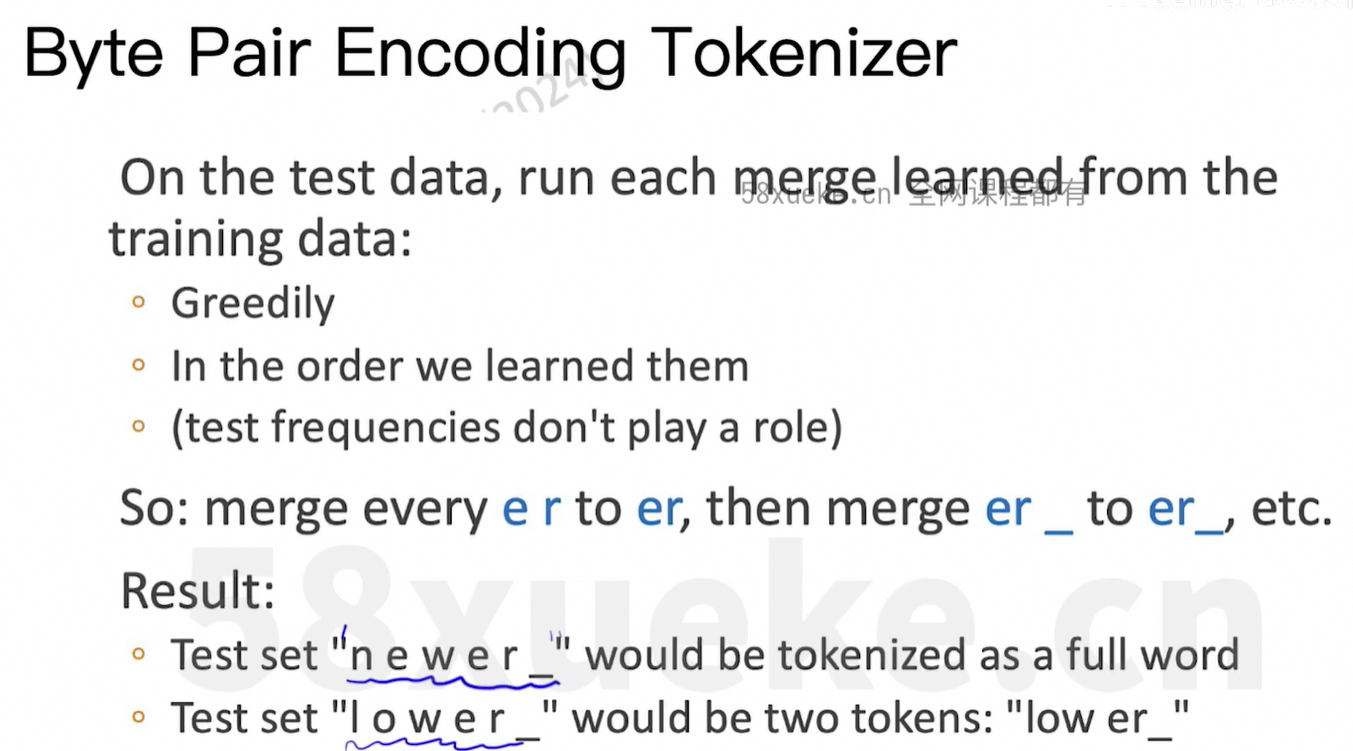
(1)Byte Pair Encoding Tokenizer
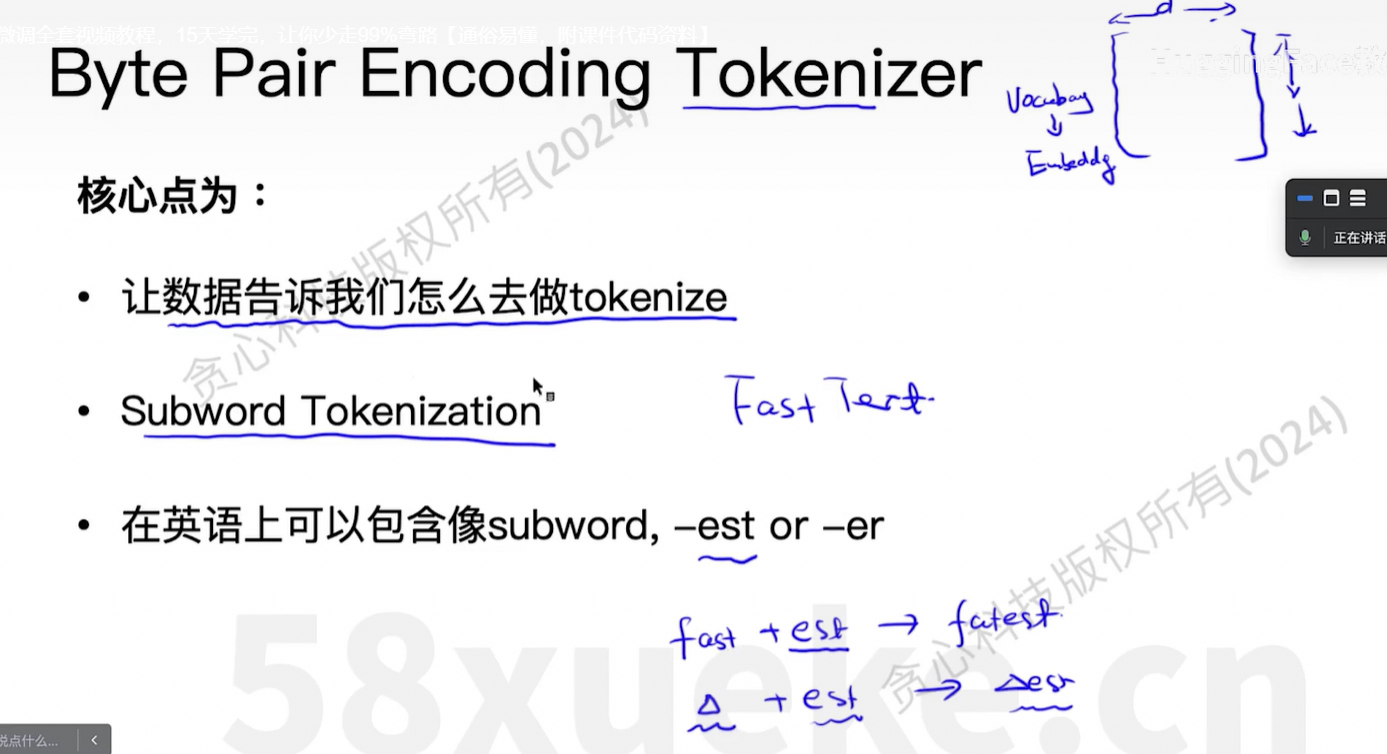
Subword方法可以有效解决Out Of Vocabulary的问题。
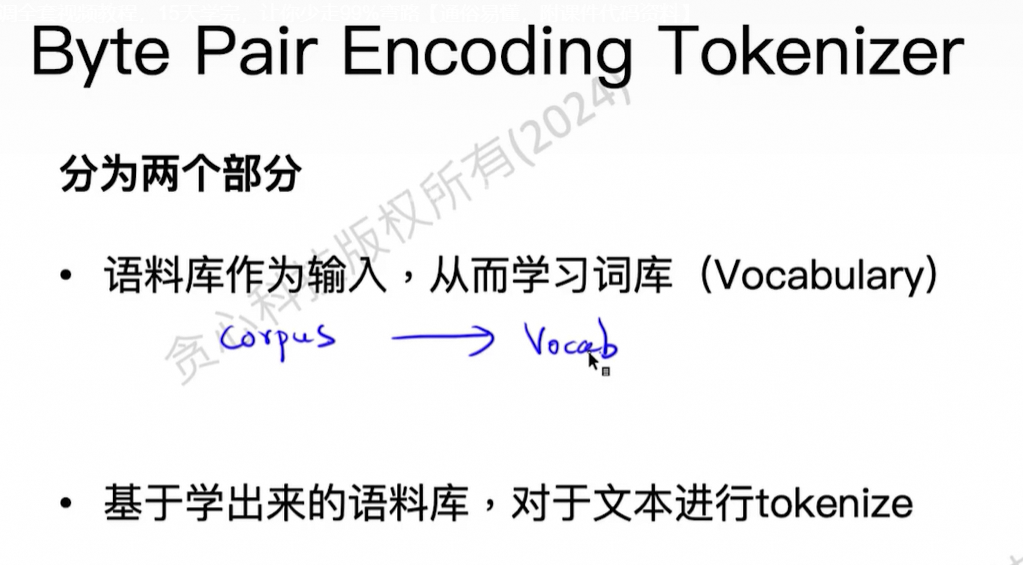
corpus=语料库
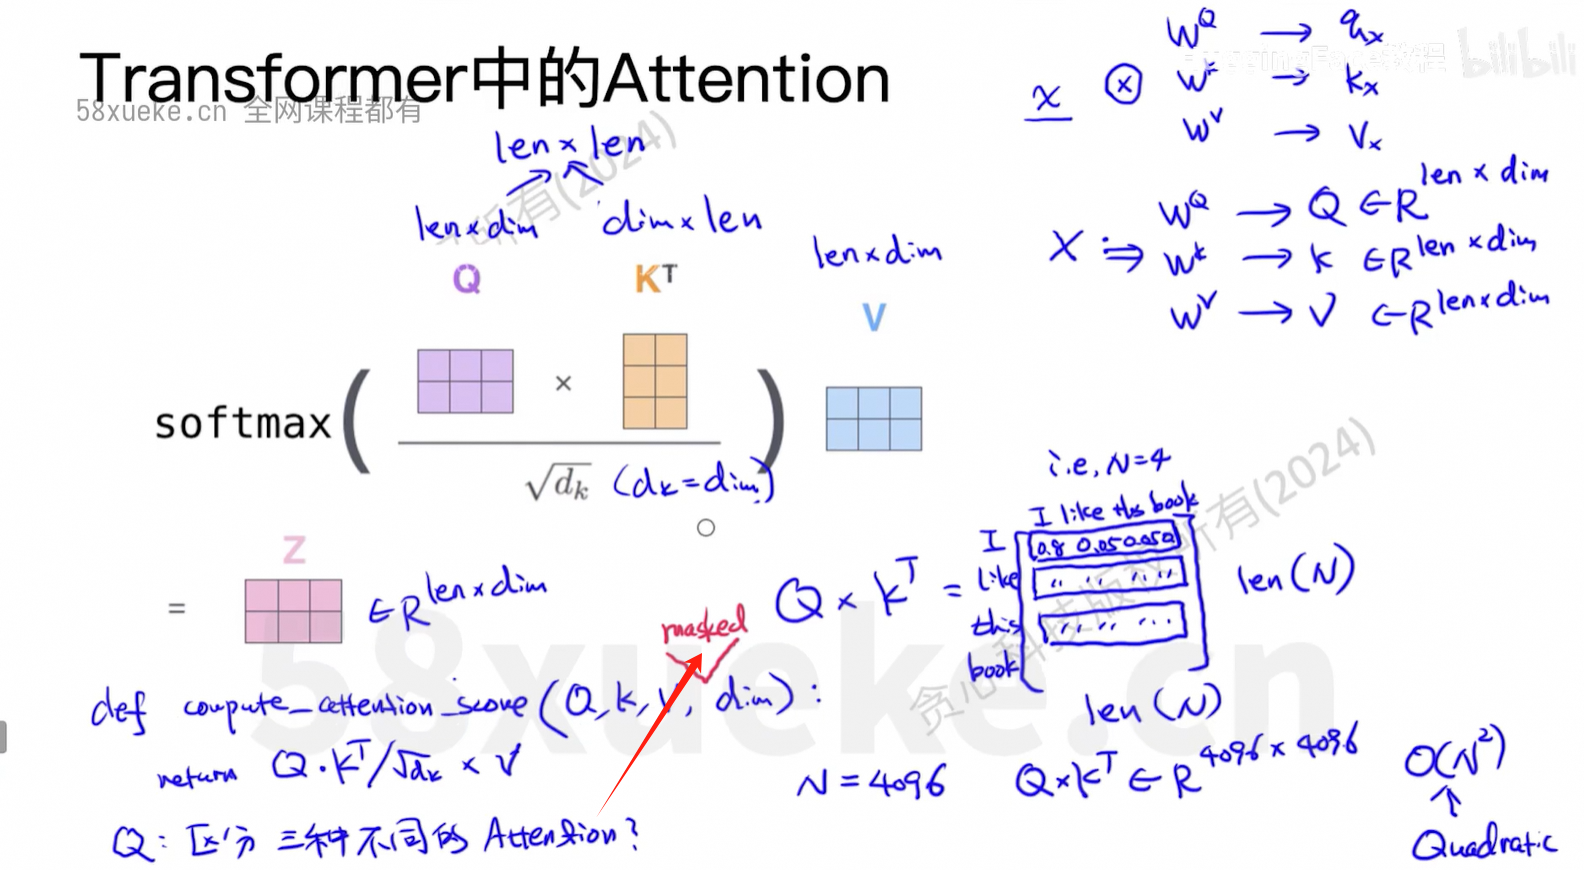
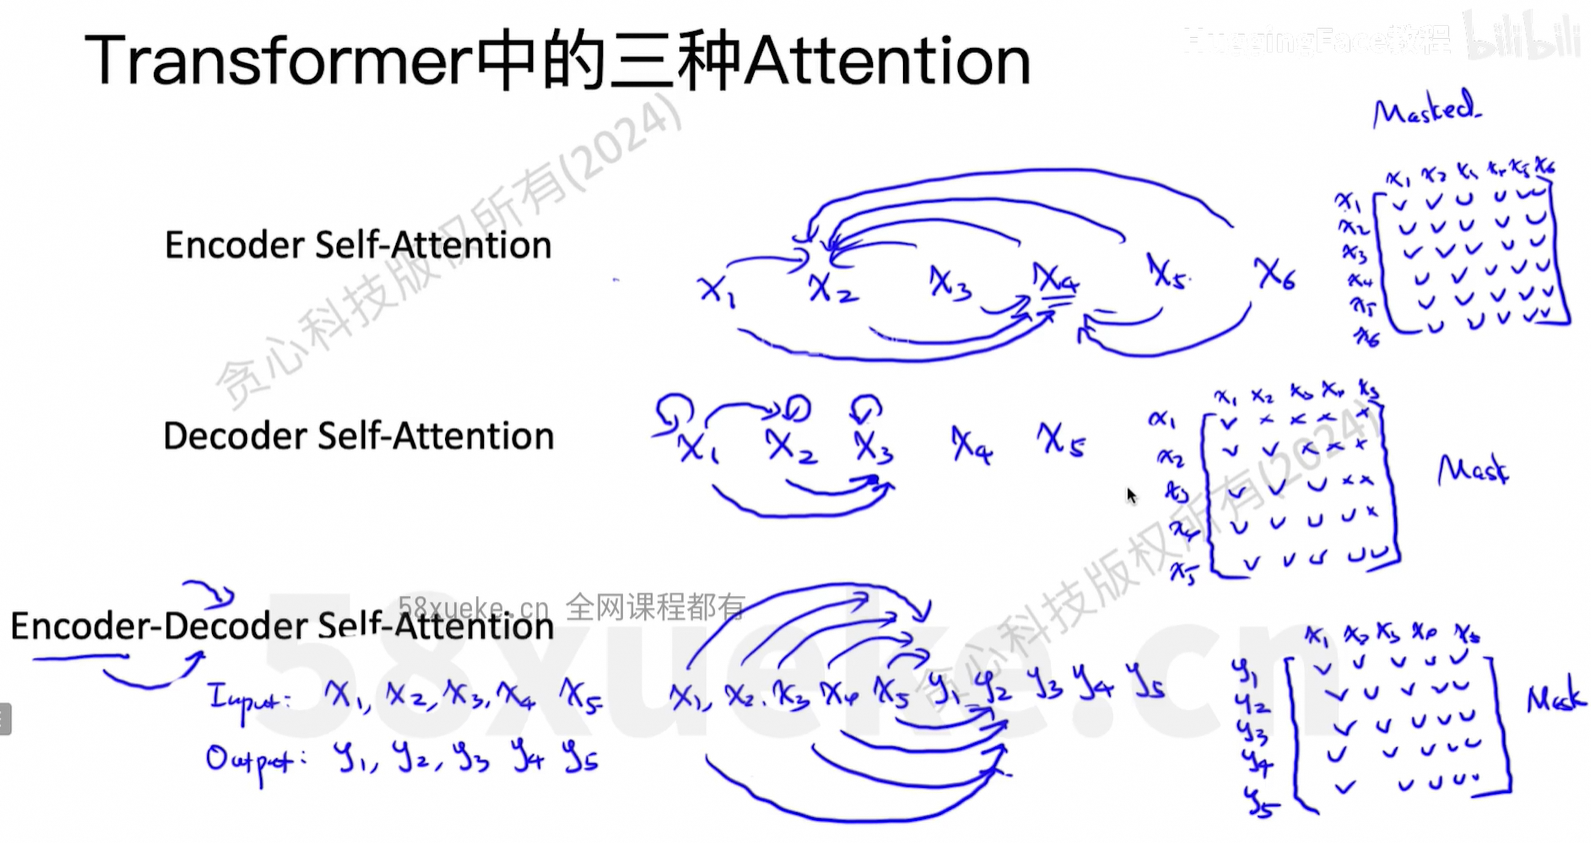
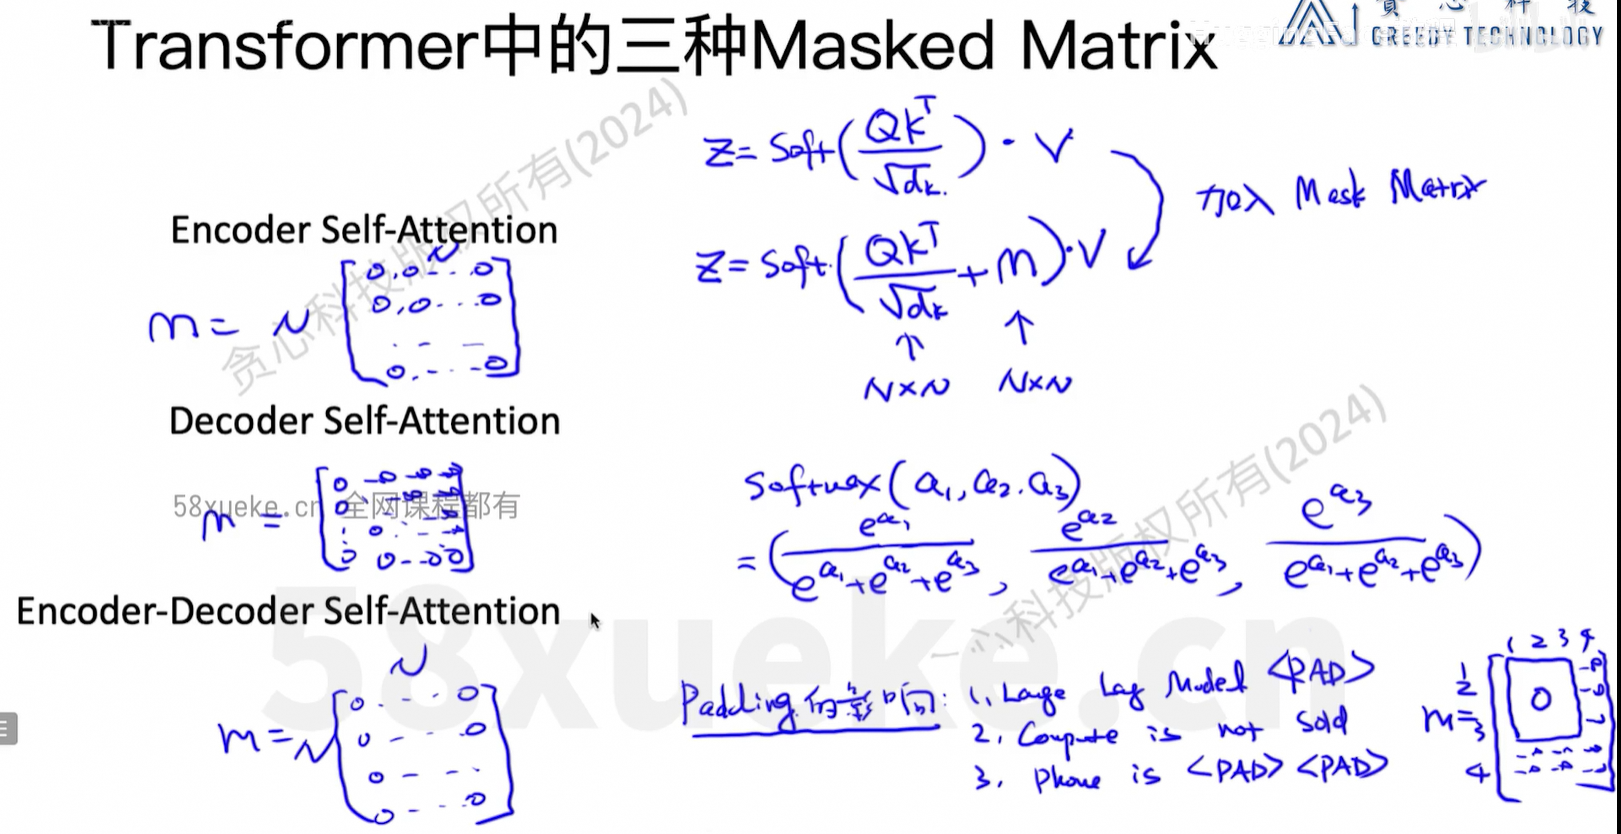
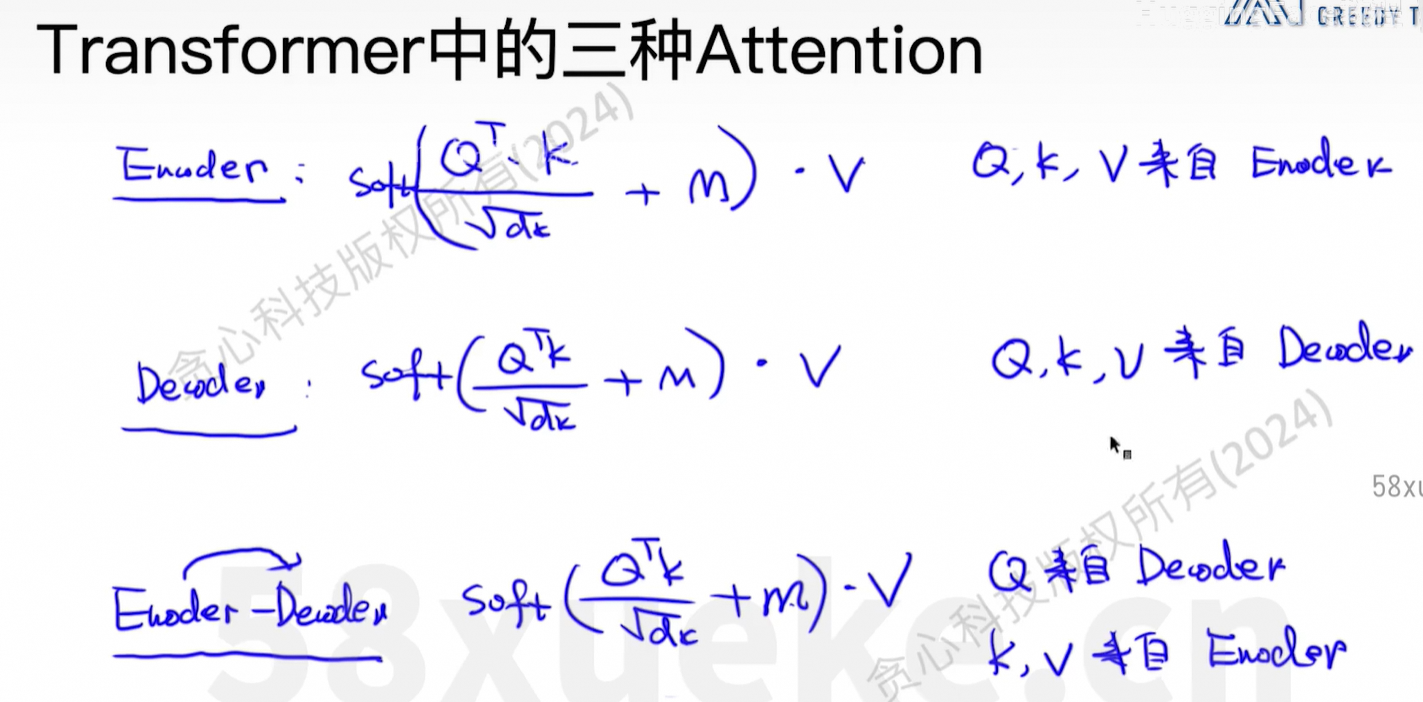
(2)Attention + Mask
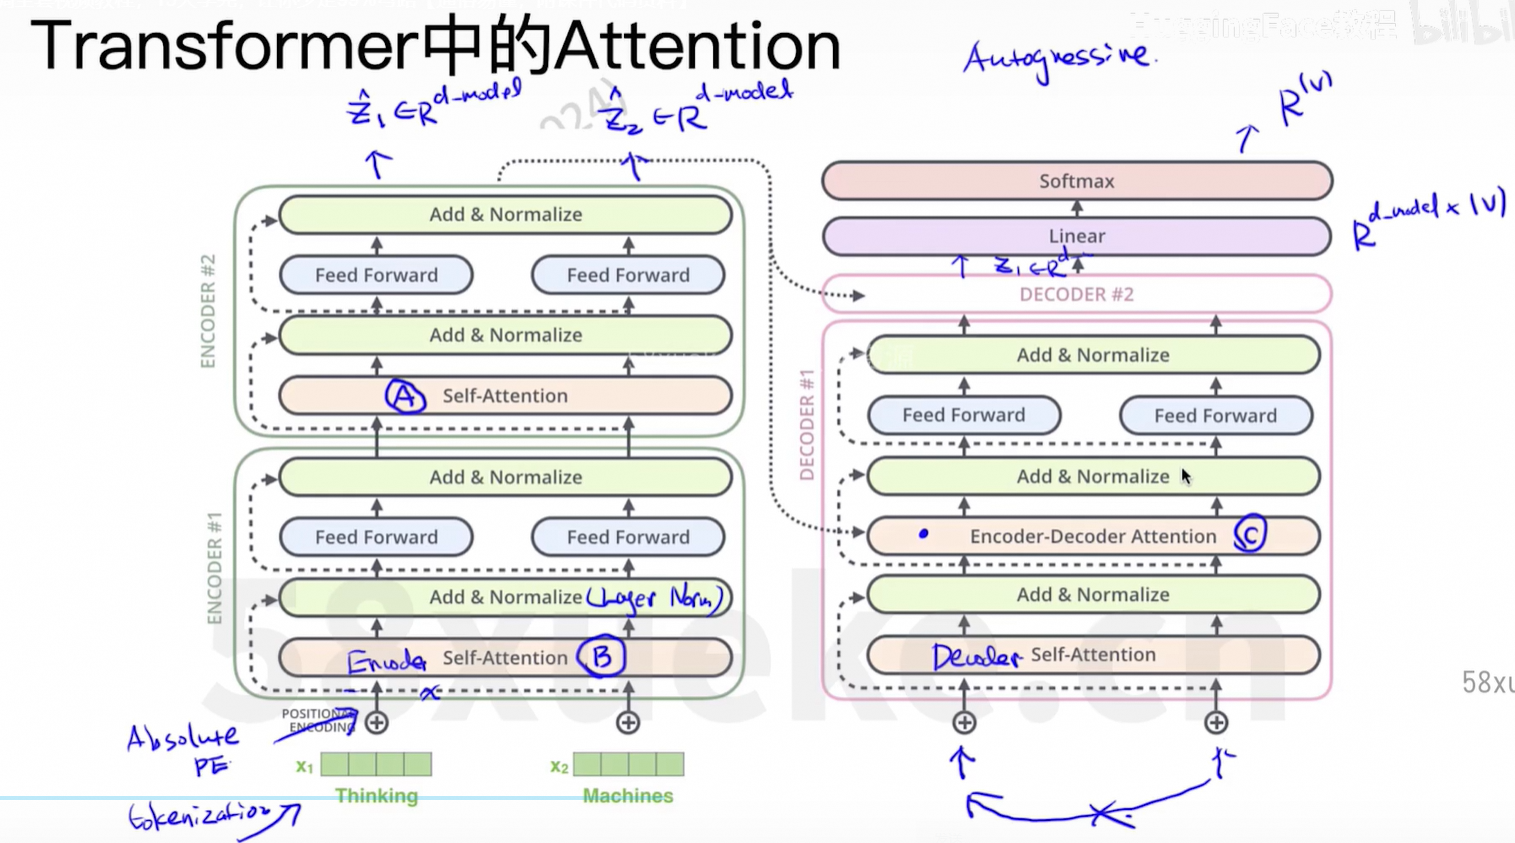
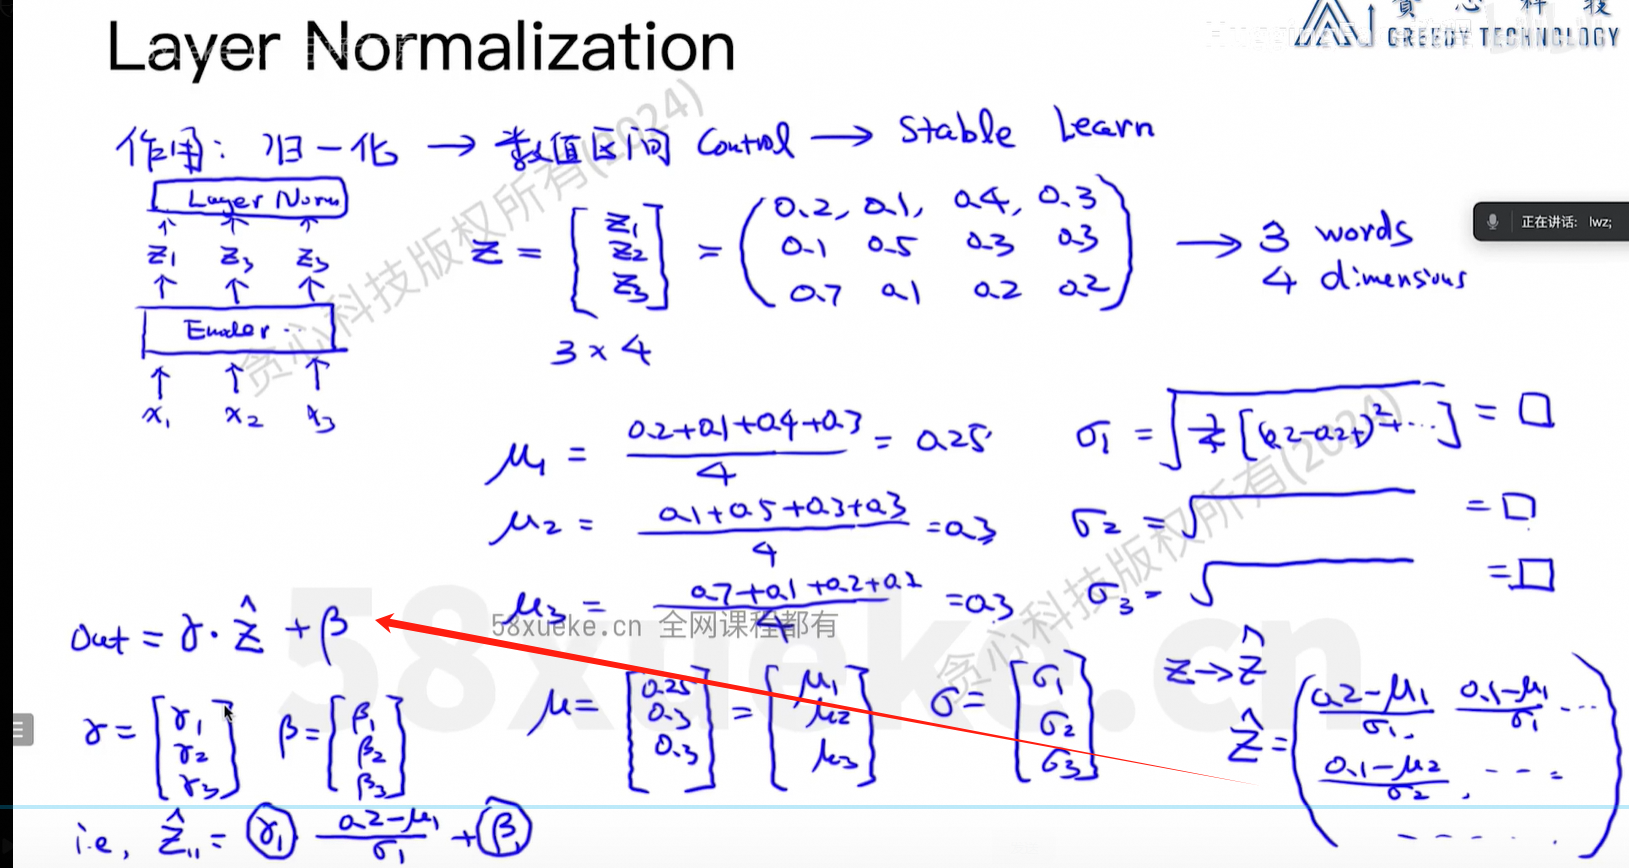
(3)Layer Normalization
第2节课:Transformer Part2
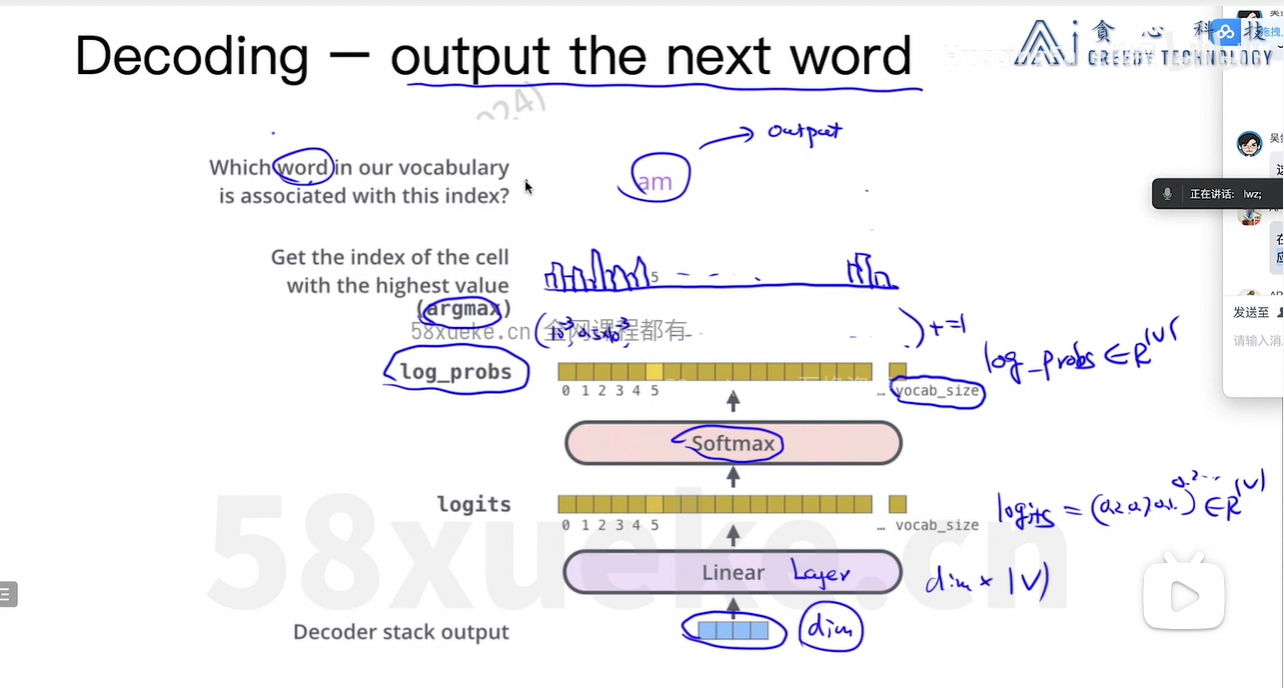
(1)Decoding
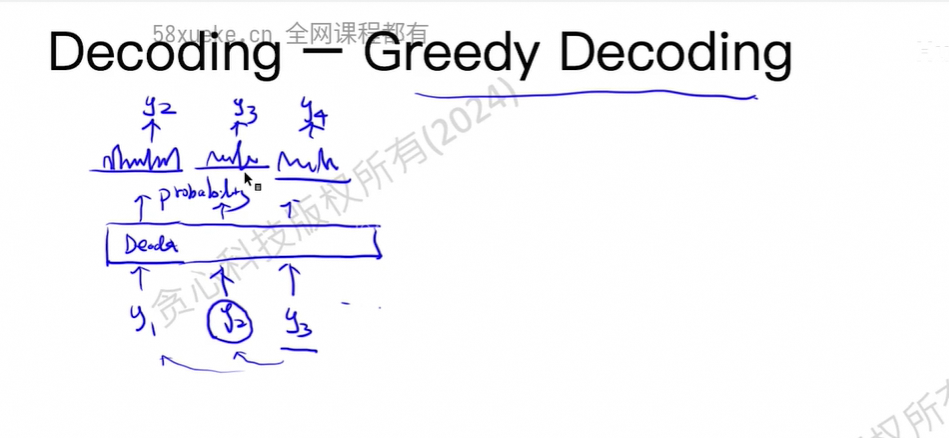
某一次最好的不一定是全局最好的。假如y2不对,那么可以导致后续的全部出错。
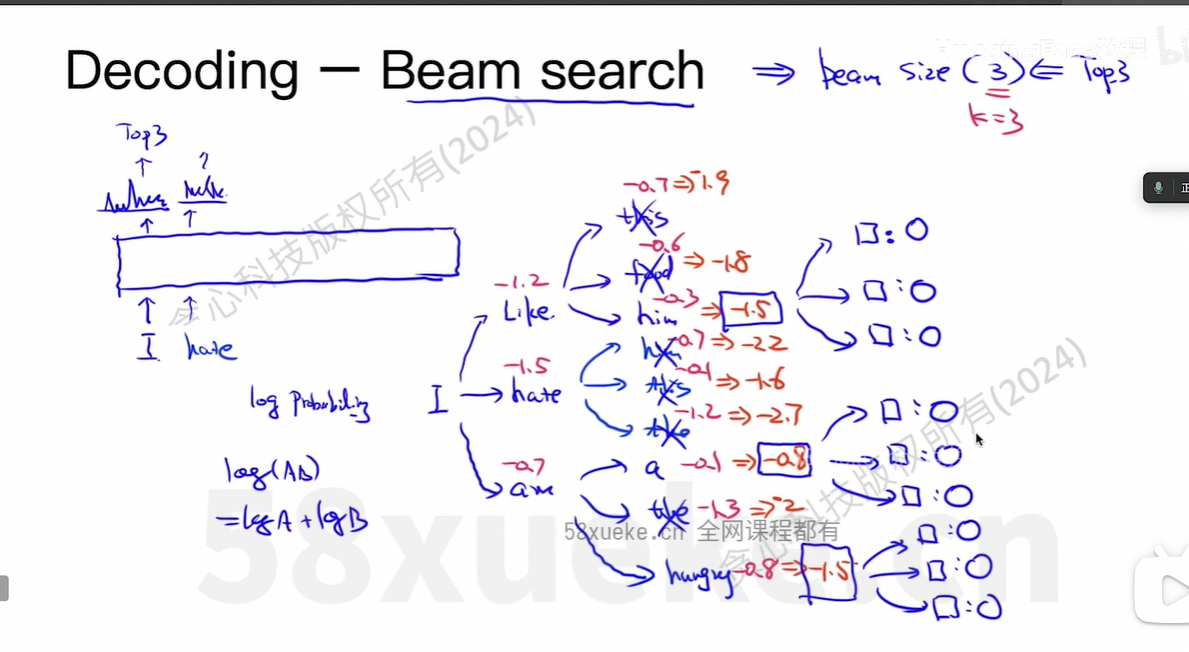
每次保留topN个,不会导致指数级增长。
(2)Label Smoothing
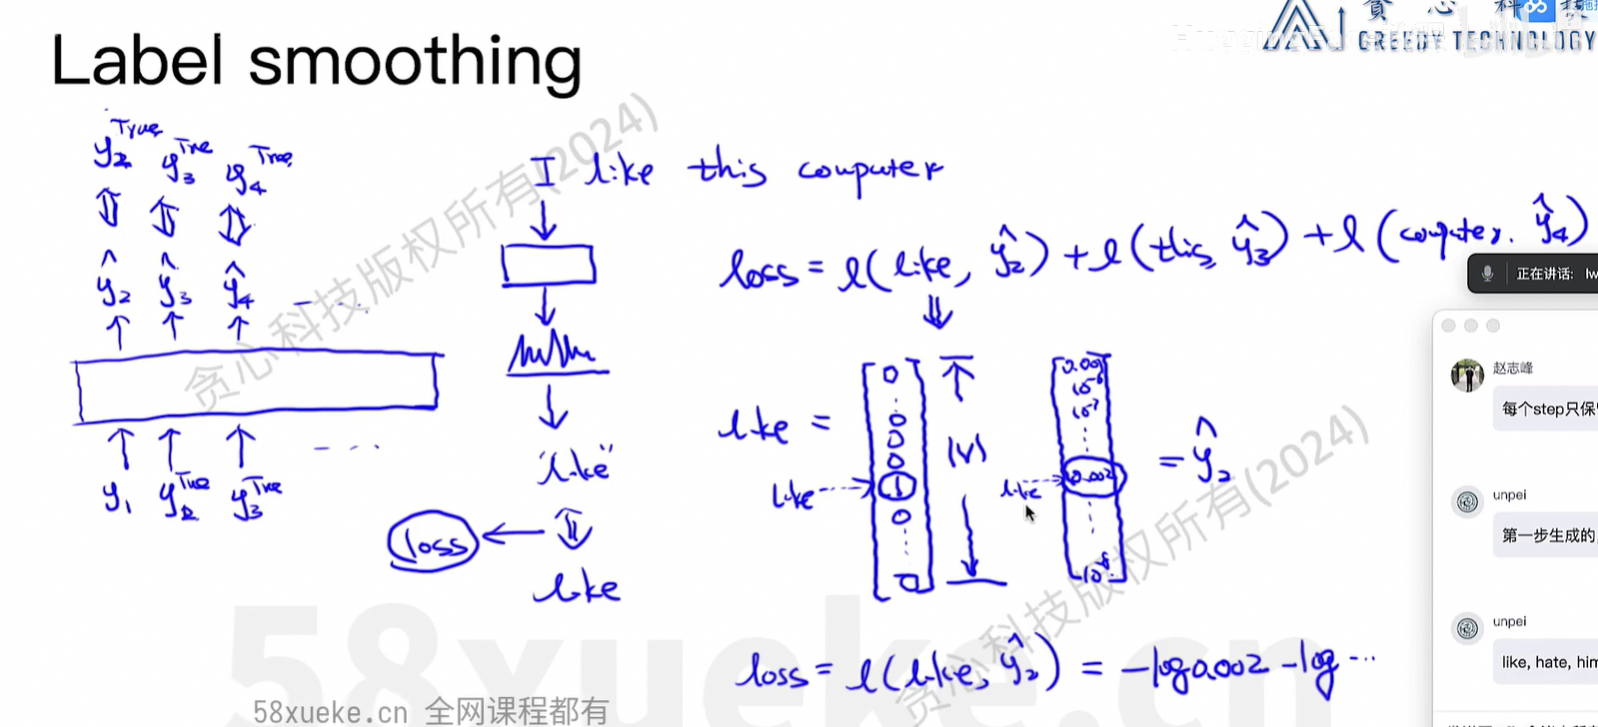
交叉熵方式。
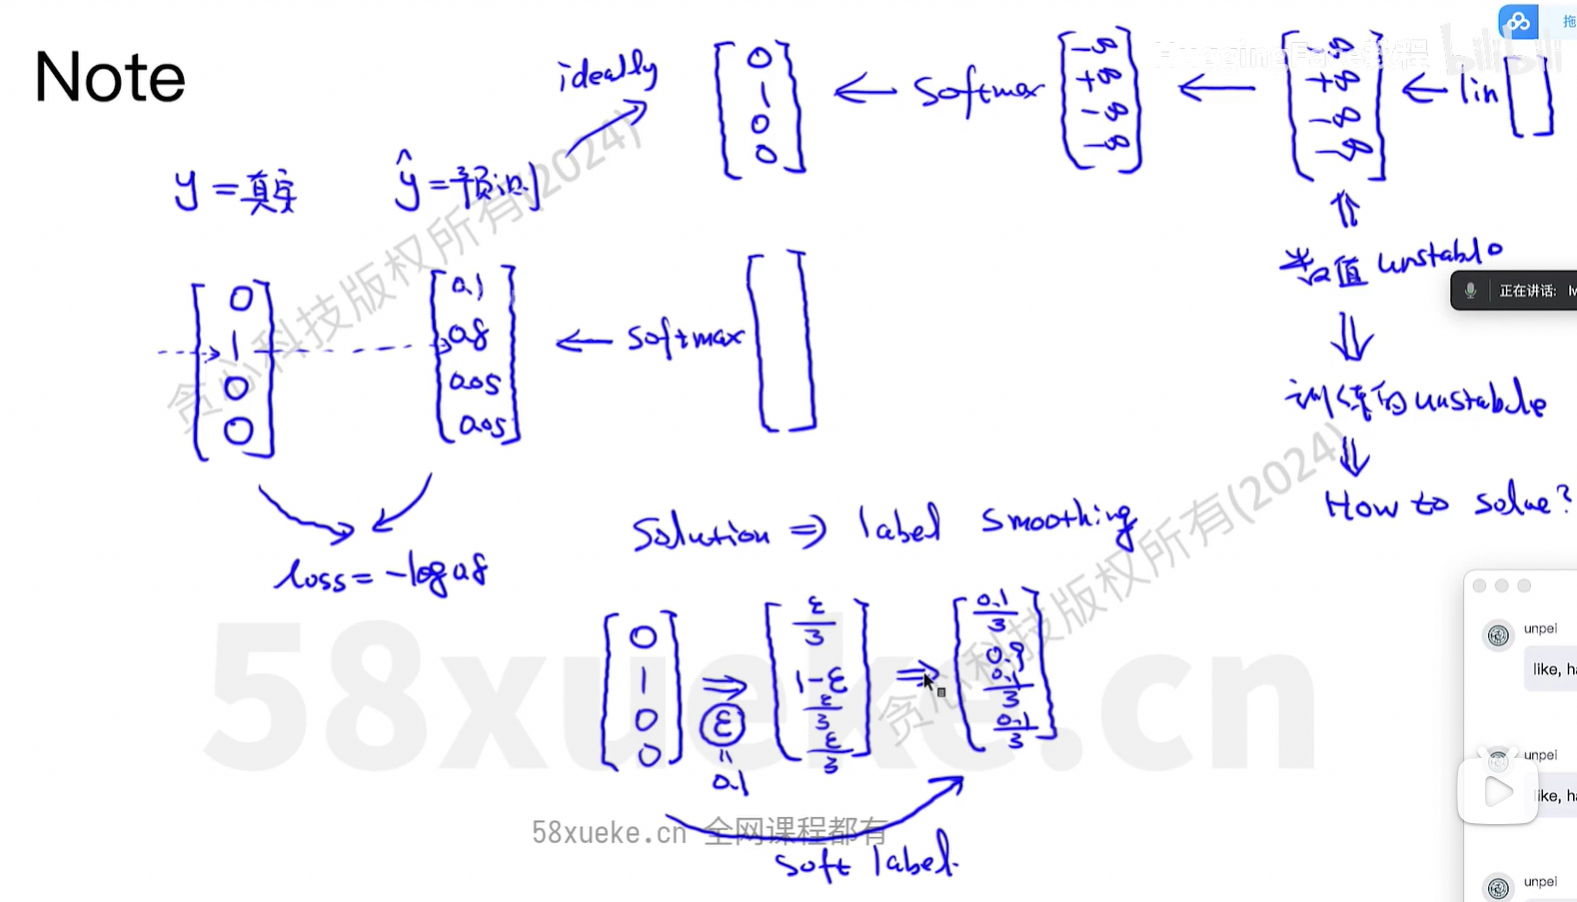
不需要拟合0-1这种极端的分布,而是稍微平缓一点的分布。
第3节课:Encoder and Decoder Based Models
观看annotated-transformer源码。
https://gitcode.com/gh_mirrors/an/annotated-transformer
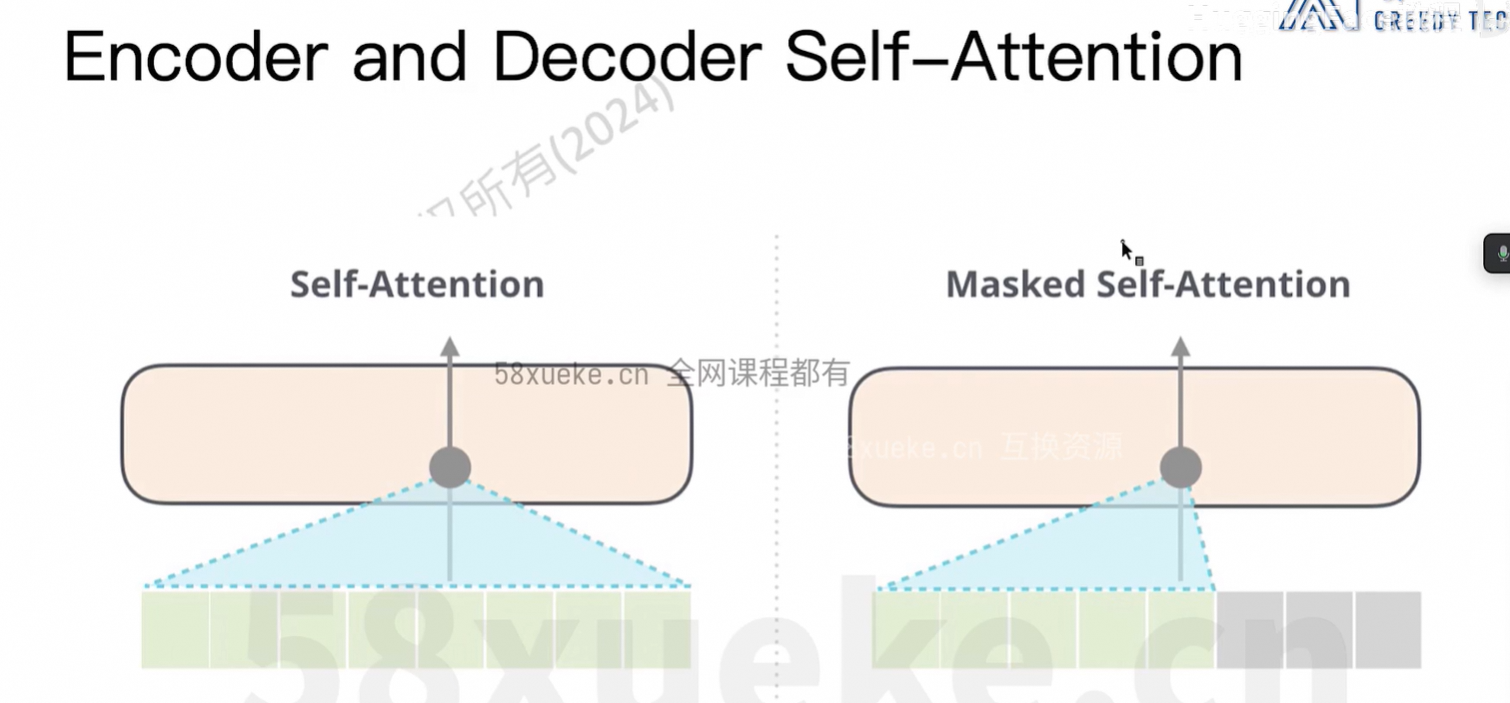
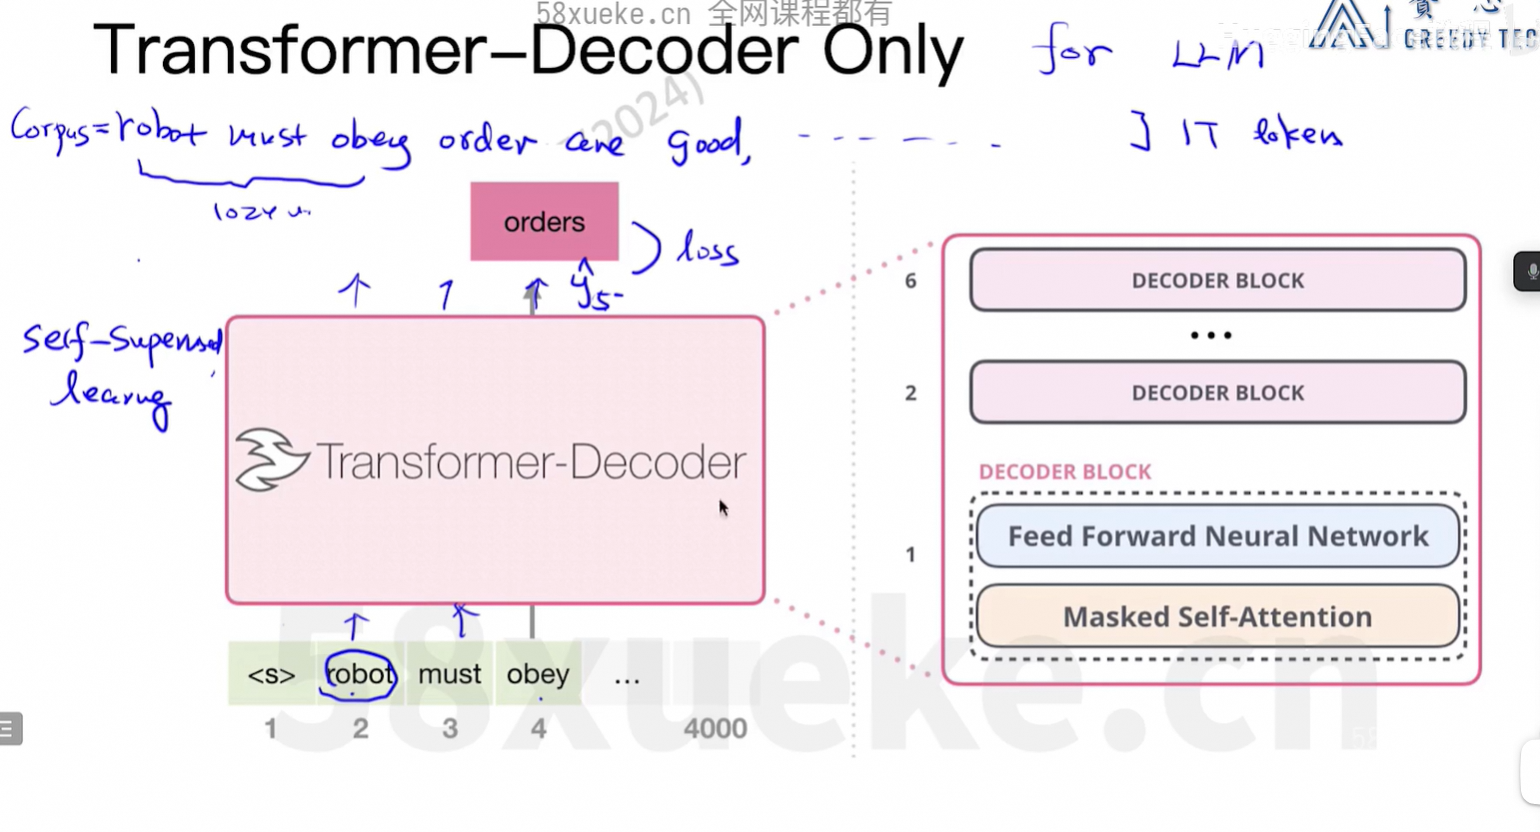
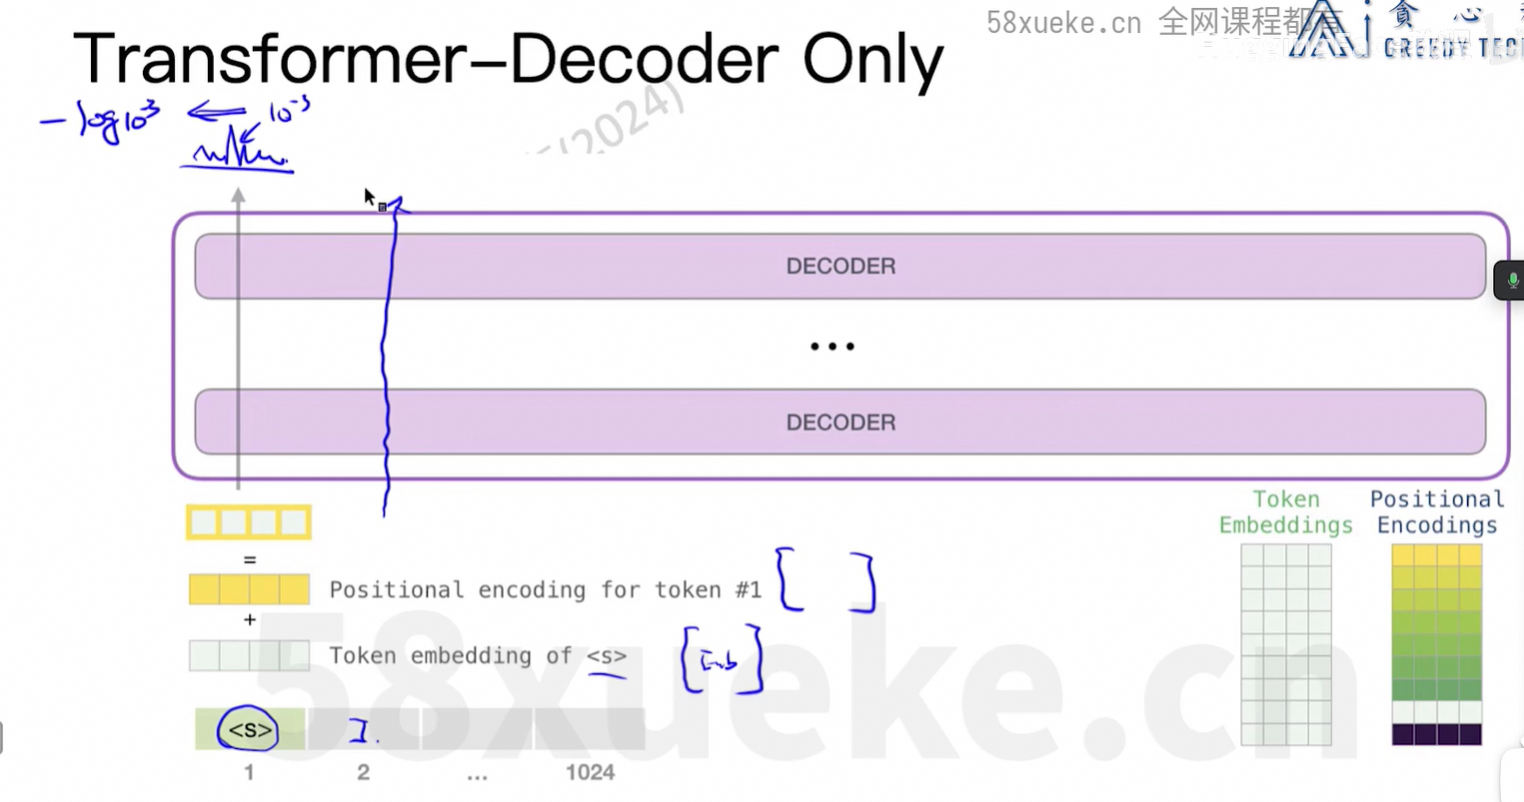
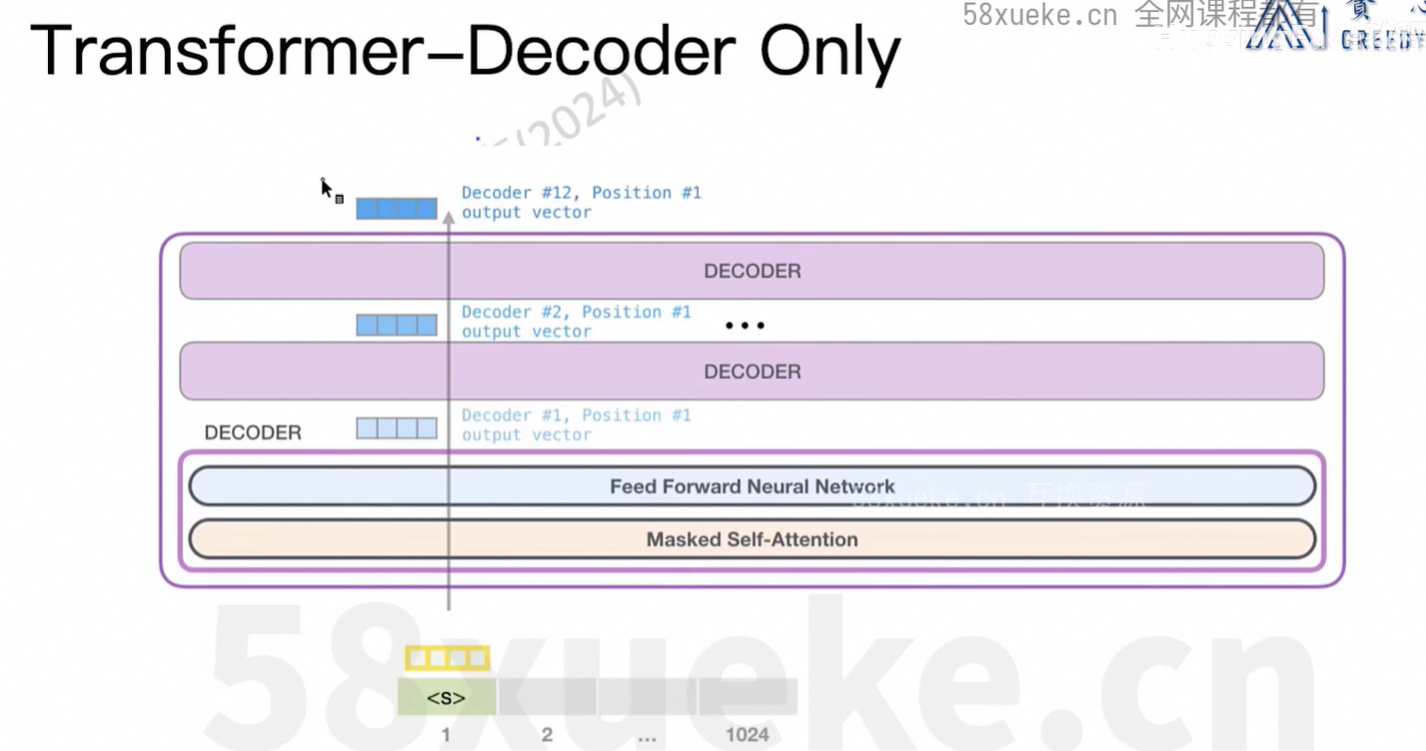
(1)Encoder and Decoder
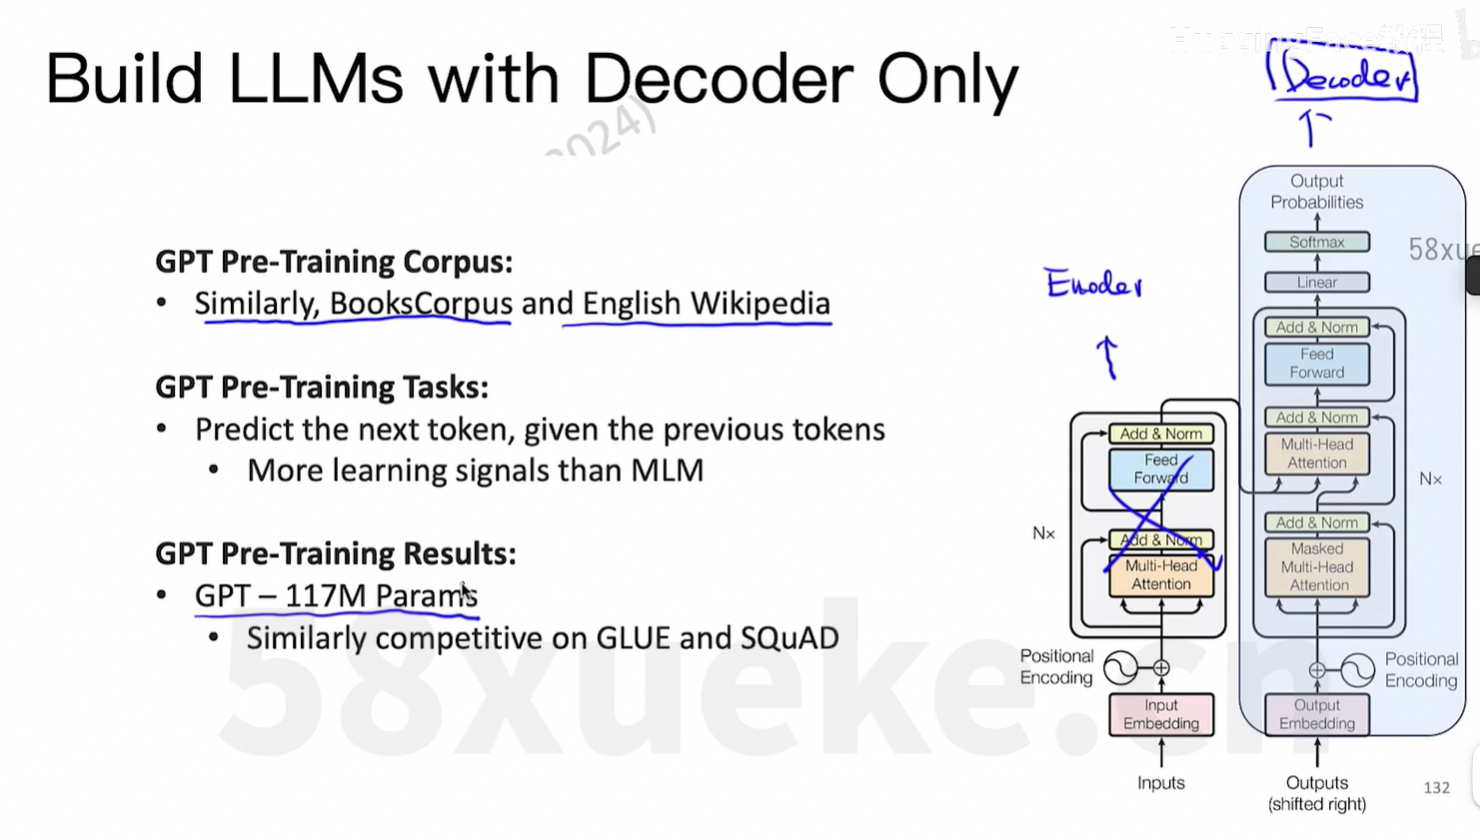
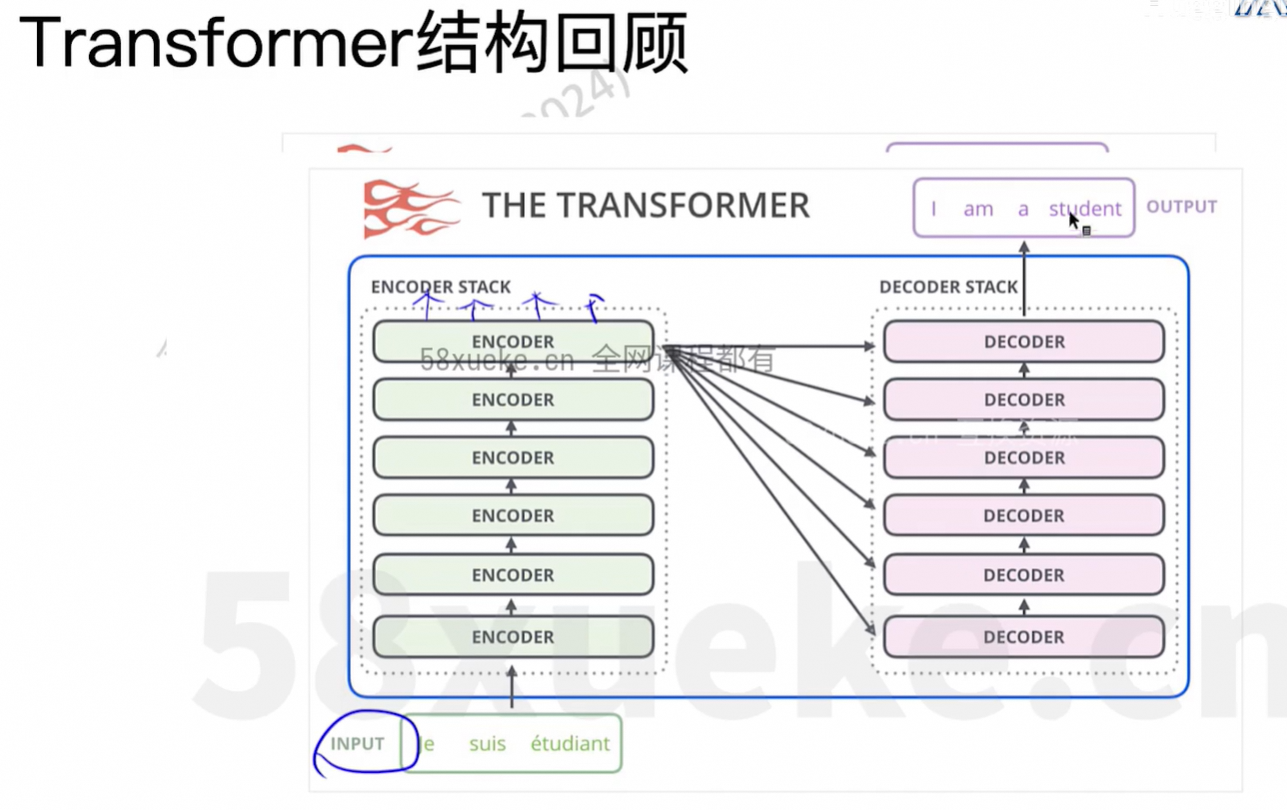
(2)Pretrain & Fine-tune
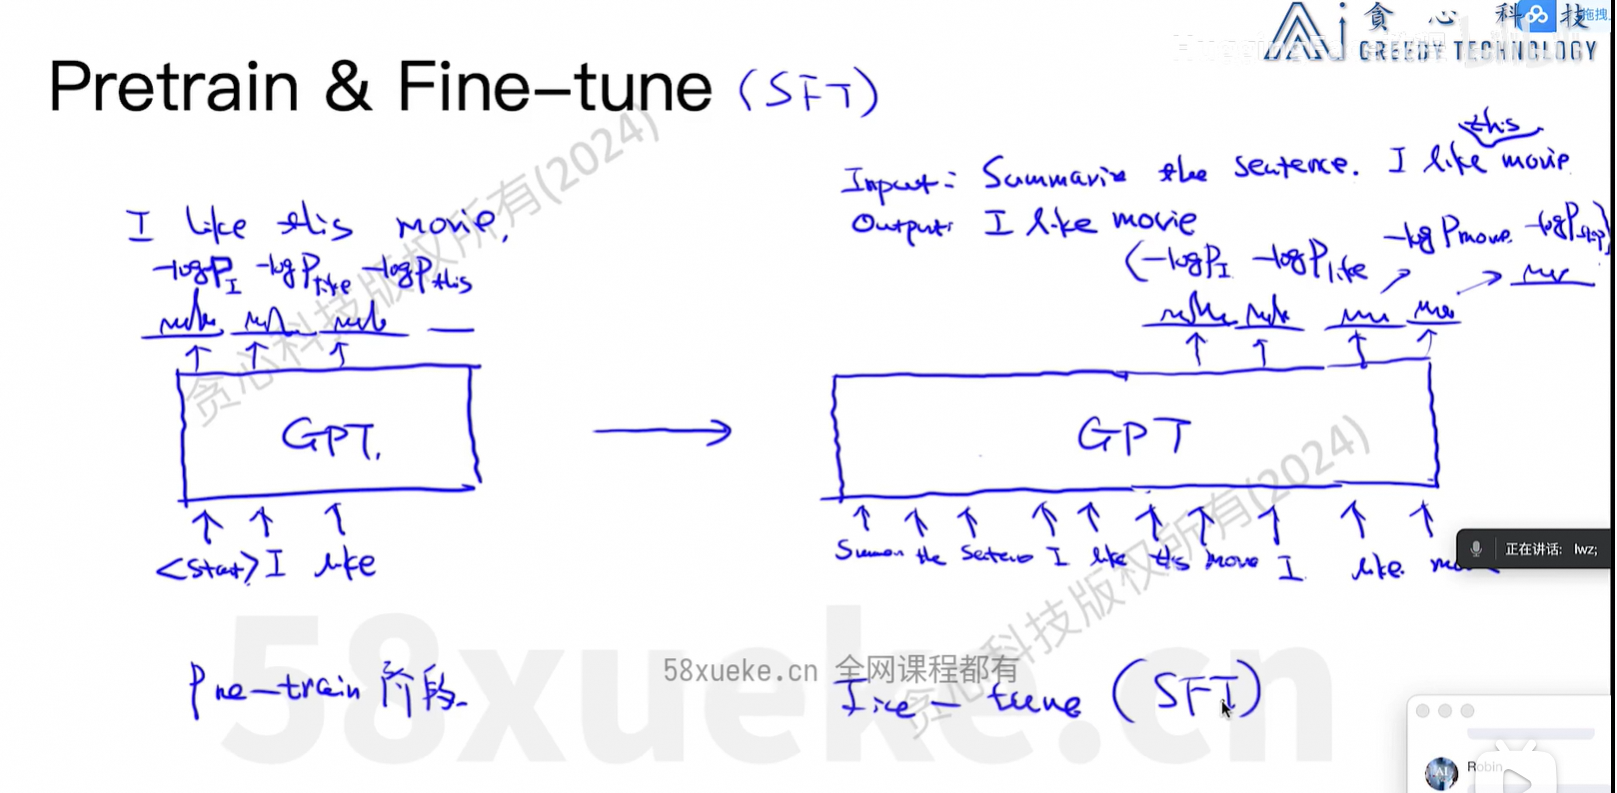
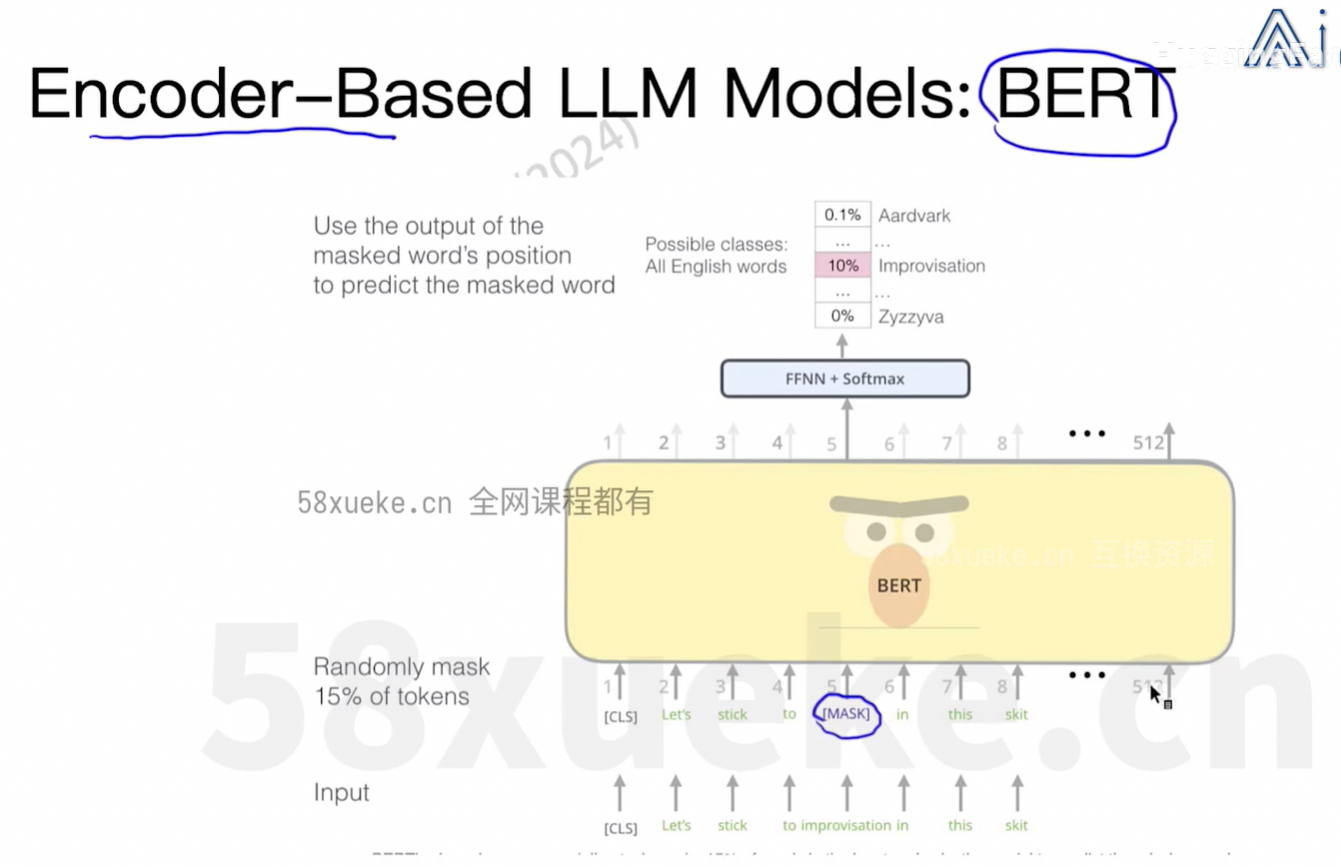
(3)Position Embedding
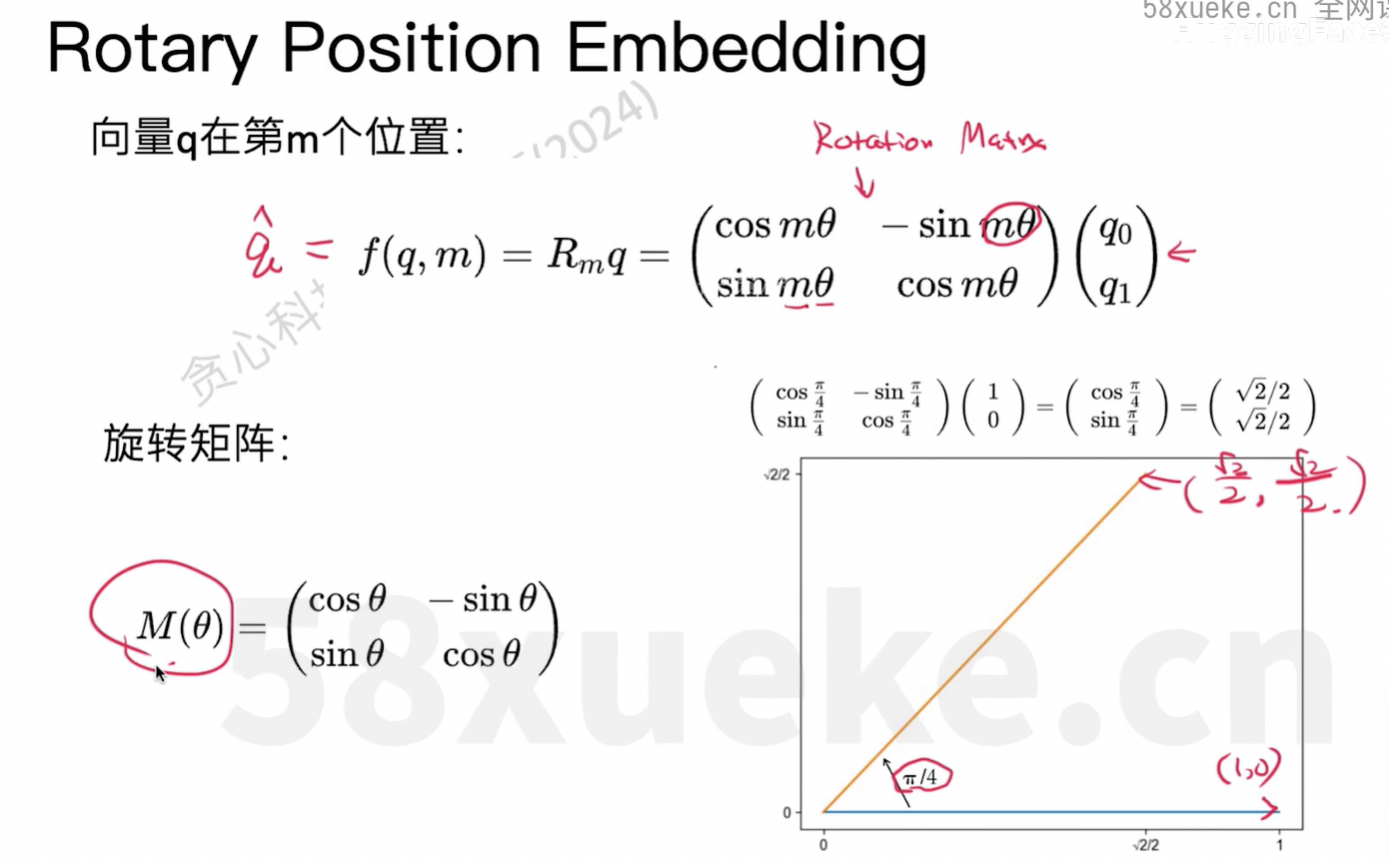
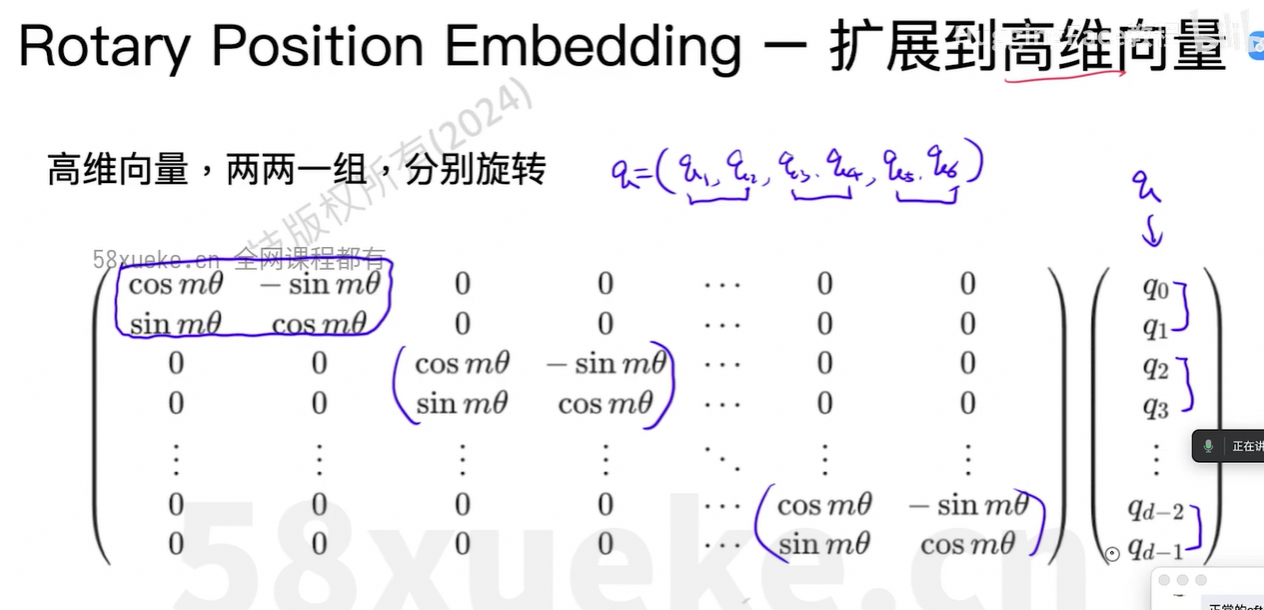
(4)Flash Attention
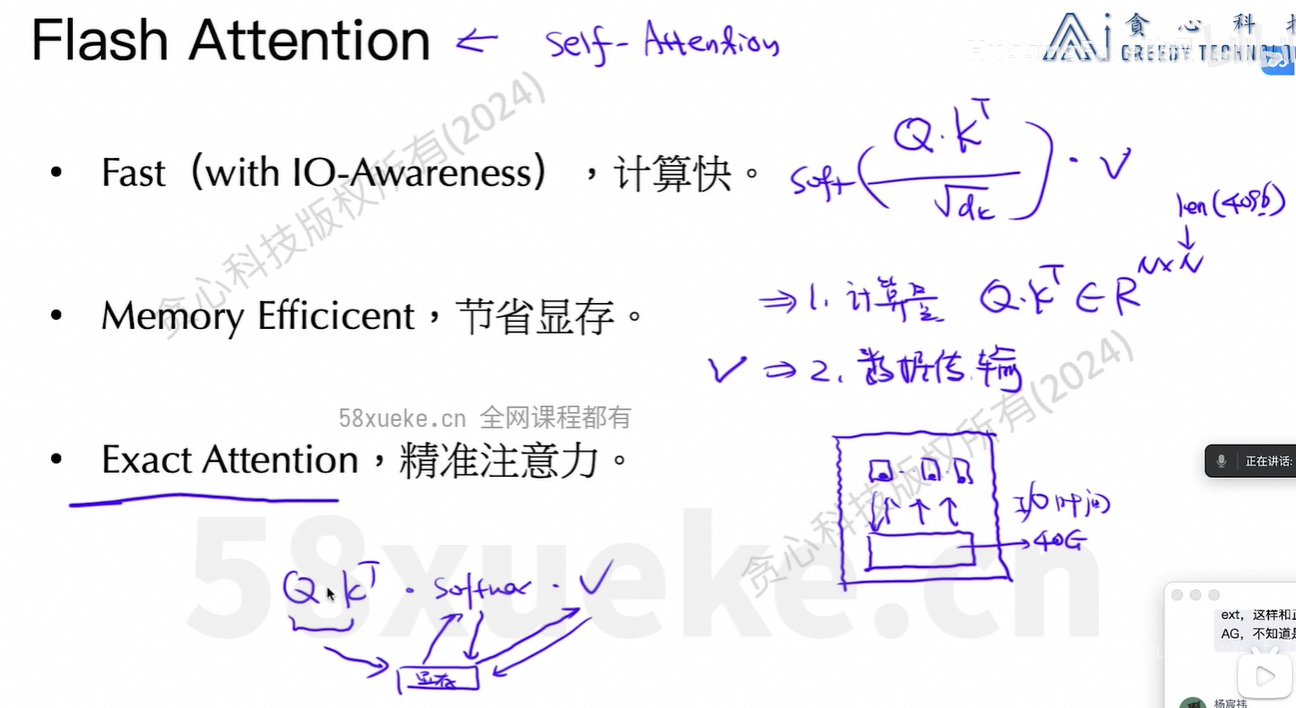
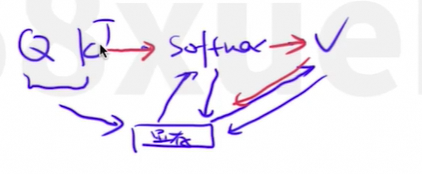
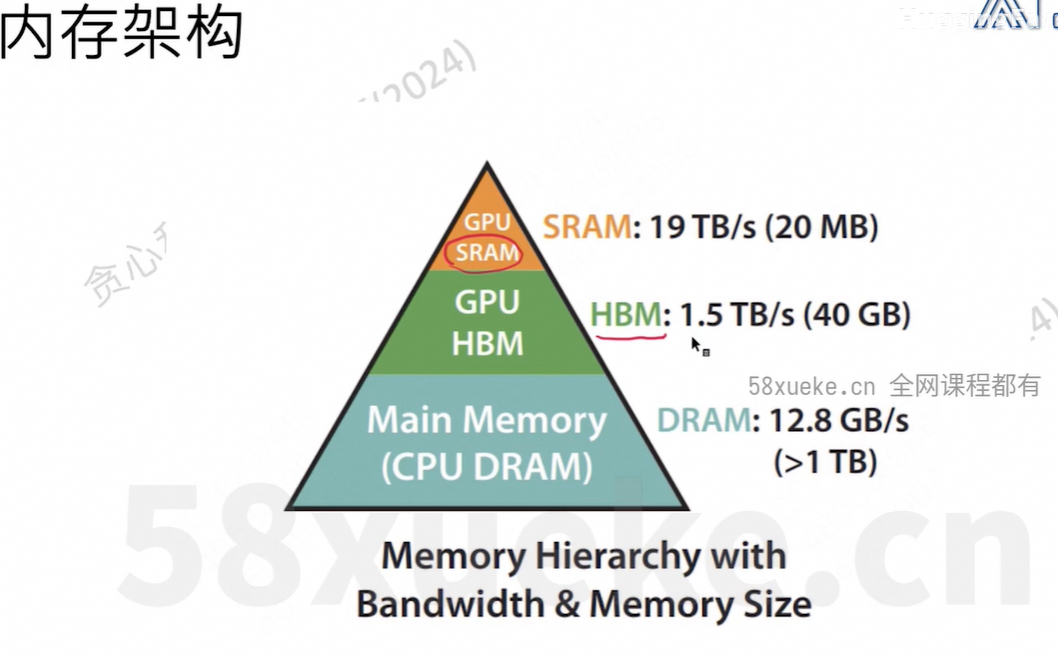
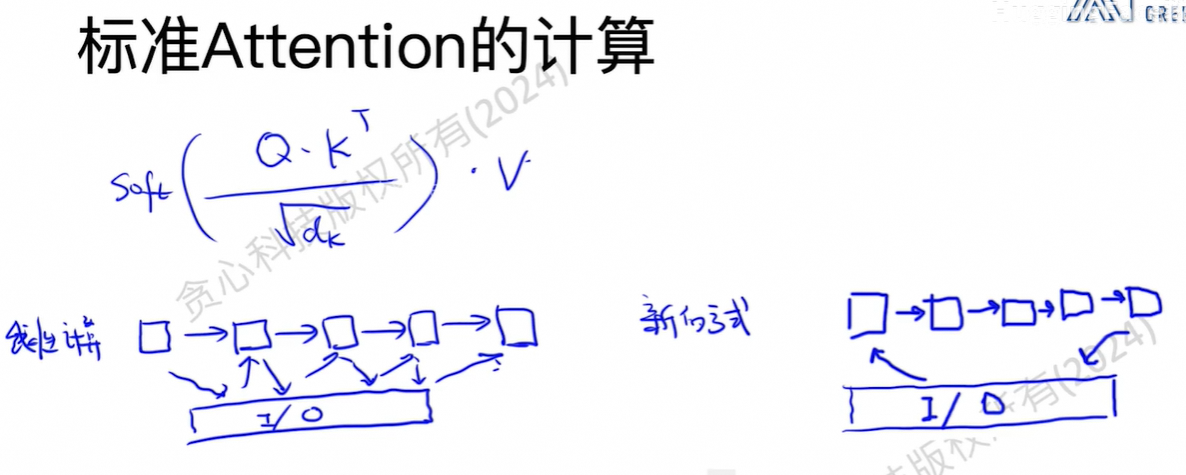
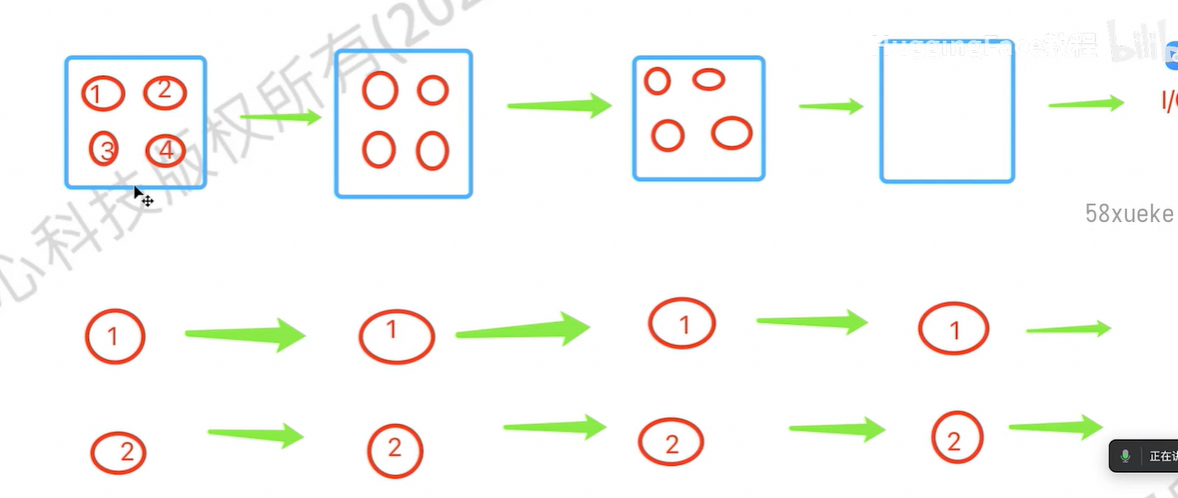
新方式下每个Block太大不能全部装进GPU SRAM。
核心思想:
训练作业
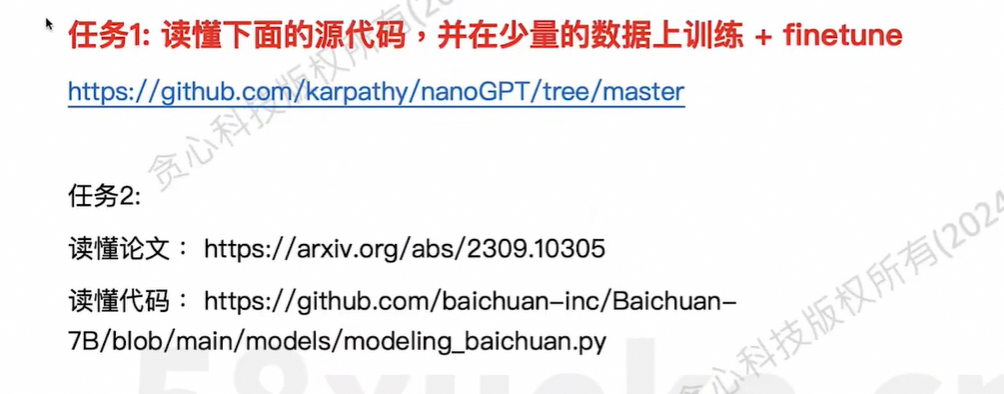
https://github.com/karpathy/nanoGPT/tree/master
https://arxiv.org/abs/2309.10305
https://github.com/baichuan-inc/Baichuan-7B/blob/main/models/modeling_baichuan.py

码道开发者社区,聚焦华为云码道 CodeArts 代码智能体,沉淀 Agent、Skill、鸿蒙开发实战内容,供开发者查阅资料、交流技术、分享工程实践
更多推荐



 4
 0
- 0


 已为社区贡献7条内容

所有评论(0)